when I’m using TensorFlow multi worker strategy does every node have to have every file or do I give certain files to each node?
submitted by /u/Mayfieldmobster
[visit reddit] [comments]
 DataBloom
when I’m using TensorFlow multi worker strategy does every node have to have every file or do I give certain files to each node?
submitted by /u/Mayfieldmobster
[visit reddit] [comments]
 At the forefront of AI innovation, NVIDIA continues to push the boundaries of technology in machine learning, self-driving cars, robotics, graphics, and more.
 NVIDIA researchers will present 20 papers at the thirty-fifth annual conference on Neural Information Processing Systems (NeurIPS) from December 6 to December 14, 2021.
Here are some of the featured papers:
Alias-Free Generative Adversarial Networks (StyleGAN3)
Tero Karras, Miika Aittala, Samuli Laine, Erik Härkönen, Janne Hellsten, Jaakko Lehtinen, Timo Aila | Paper | GitHub | Blog
StyleGAN3, a model developed by NVIDIA Research, will be presented on Tuesday, December 7 from 12:40 AM – 12:55 AM PST, advances the state-of-the-art in generative adversarial networks used to synthesize realistic images. The breakthrough brings graphics principles in signal processing and image processing to GANs to avoid aliasing: a kind of image corruption often visible when images are rotated, scaled or translated.
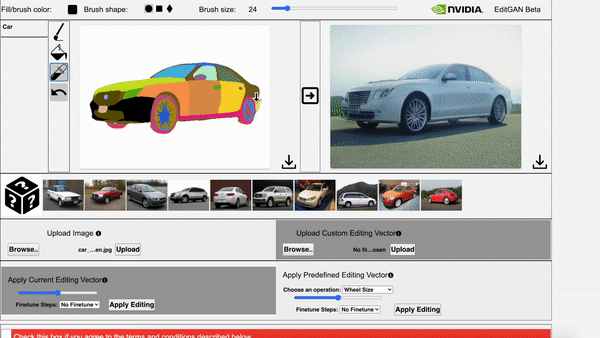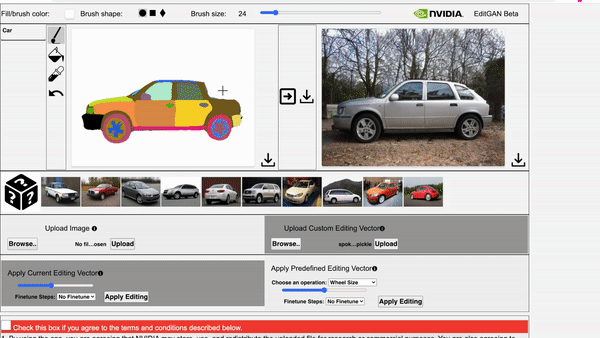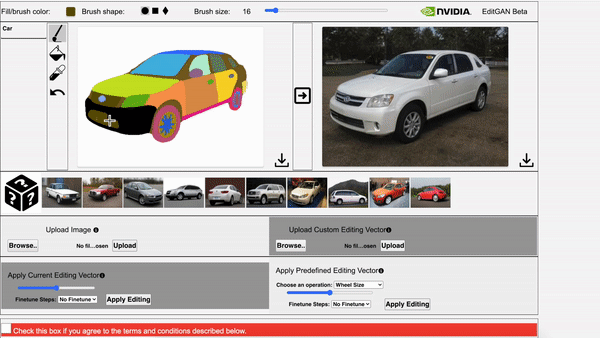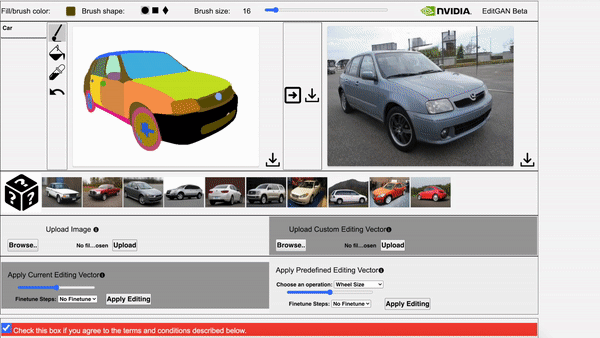
EditGAN: High-Precision Semantic Image Editing
Huan Ling*, Karsten Kreis*, Daiqing Li, Seung Wook Kim, Antonio Torralba, Sanja Fidler | Paper | GitHub
EditGAN, a novel method for high quality, high precision semantic image editing, allowing users to edit images by modifying their highly detailed part segmentation masks, e.g., drawing a new mask for the headlight of a car. EditGAN builds on a GAN framework that jointly models images and their semantic segmentations, requiring only a handful of labeled examples, making it a scalable tool for editing. The poster session will be held on Thursday, December 9 from 8:30 AM – 10:00 AM PST.
SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers
Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo | Paper | GitHub
SegFormer, a simple, efficient yet powerful semantic segmentation framework which unifies Transformers with lightweight multilayer perception (MLP) decoders. SegFormer has two appealing features: 1) SegFormer comprises a novel hierarchically structured Transformer encoder which outputs multiscale features. It does not need positional encoding, thereby avoiding the interpolation of positional codes which leads to decreased performance when the testing resolution differs from training. 2) SegFormer avoids complex decoders. The poster will be presented on Tuesday, December 7 from 8:30 AM – 10:00 AM PST.
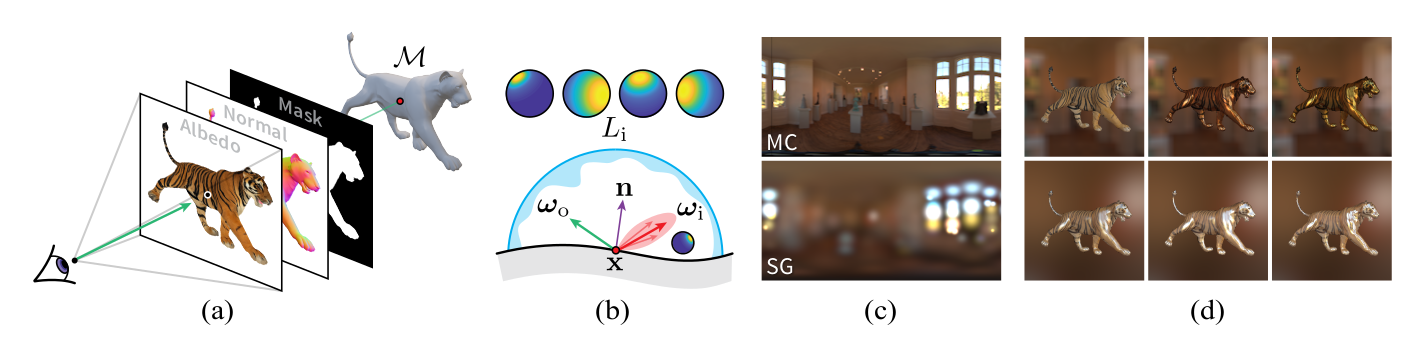
DIB-R++: Learning to Predict Lighting and Material with a Hybrid Differentiable Renderer
Wenzheng Chen, Joey Litalien, Jun Gao, Zian Wang, Clement Fuji Tsang, Sameh Khamis, Or Litany, Sanja Fidler | Paper
DIB-R++, a deferred, image-based renderer which supports these photorealistic effects by combining rasterization and ray-tracing, taking advantage of their respective strengths—speed and realism. The poster session is on Thursday, December 9 from 4:30 PM – 6:00 PM PST.
In addition to the papers at NeurIPS 2021, researchers and developers can accelerate 3D deep learning research with new Kaolin features:
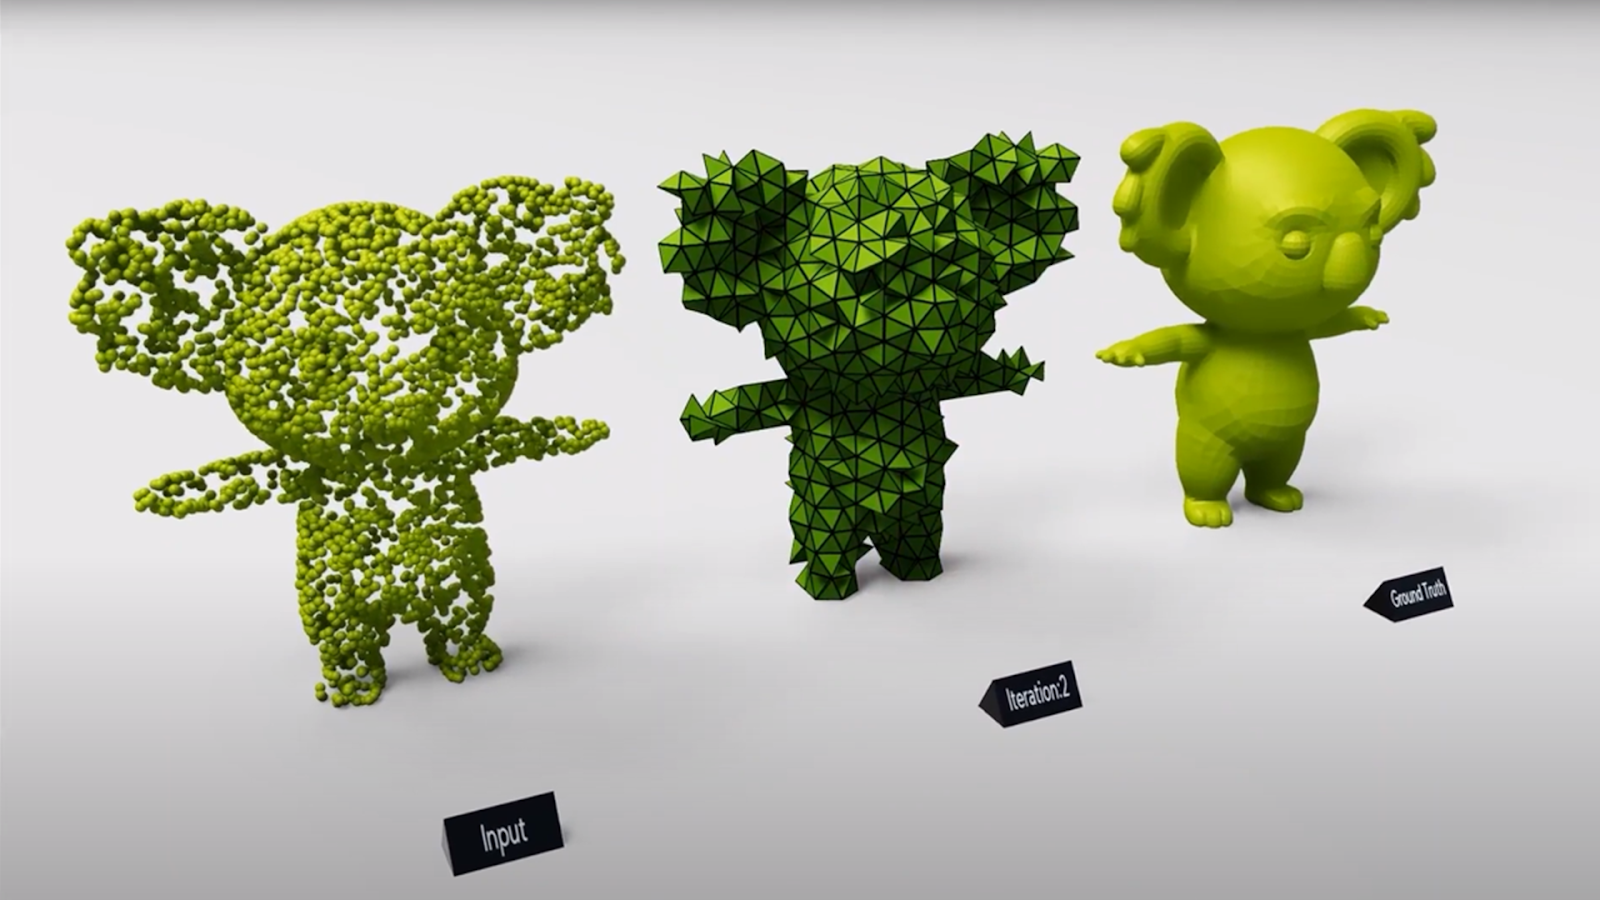
Kaolin is launching new features to accelerate 3D deep learning research. Updates to the NVIDIA Omniverse Kaolin app will bring robust visualization of massive point clouds. Updates to the Kaolin library will include support for tetrahedral meshes, rays management functionality, and a strong speedup to DIB-R. To learn more about Kaolin, watch the recent GTC session.
To view the complete list of NVIDIA Research accepted papers, workshop and tutorials, demos, and to explore job opportunities at NVIDIA, visit the NVIDIA at NeurIPS 2021 website.
I am trying to increase the training speed of my model by using mixed precision and the nvidia gpu tensor cores. For this, I just use the keras mixed precision, but the speed increment is only of 10%. Then I found the nividia ngc container, which is optimized for their gpus, and with mixed precision I can increase the training speed a 60%, although with float32 the speed in lower than native. I would like to have at least the speed increase of ngc container natively, what do I need to do?
submitted by /u/diepala
[visit reddit] [comments]
hi, i tried to load model on cpu with tf.device while inference of 500 images , the cpu usage resches to 100% , inference time is 0.6sec and how do I minimize the inference time and also the utilization of cpu .
submitted by /u/nanitiru18
[visit reddit] [comments]
 Dive deep into the new features and use cases available for networking, security, storage in the latest release of the DOCA software framework.
Today, NVIDIA released the NVIDIA DOCA 1.2 software framework for NVIDIA BlueField DPUs, the world’s most advanced data processing unit (DPU). Designed to enable the NVIDIA BlueField ecosystem and developer community, DOCA is the key to unlocking the potential of the DPU by offering services to offload, accelerate, and isolate infrastructure applications services from the CPU.
DOCA is a software framework that brings together APIs, drivers, libraries, sample code, documentation, services, and prepackaged containers to simplify and speed up application development and deployment on BlueField DPUs on every data center node. Together, DOCA and BlueField create an isolated and secure services domain for networking, security, storage, and infrastructure management that is ideal for enabling a zero-trust strategy.
The DOCA 1.2 release introduces several important features and use cases.
A modern approach to security based on zero trust principles is critical to securing today’s data centers, as resources inside the data center can no longer be trusted automatically. App Shield enables detection of attacks on critical services in a system. In many systems, those critical services are responsible for ensuring the integrity and privacy of the execution of many applications.
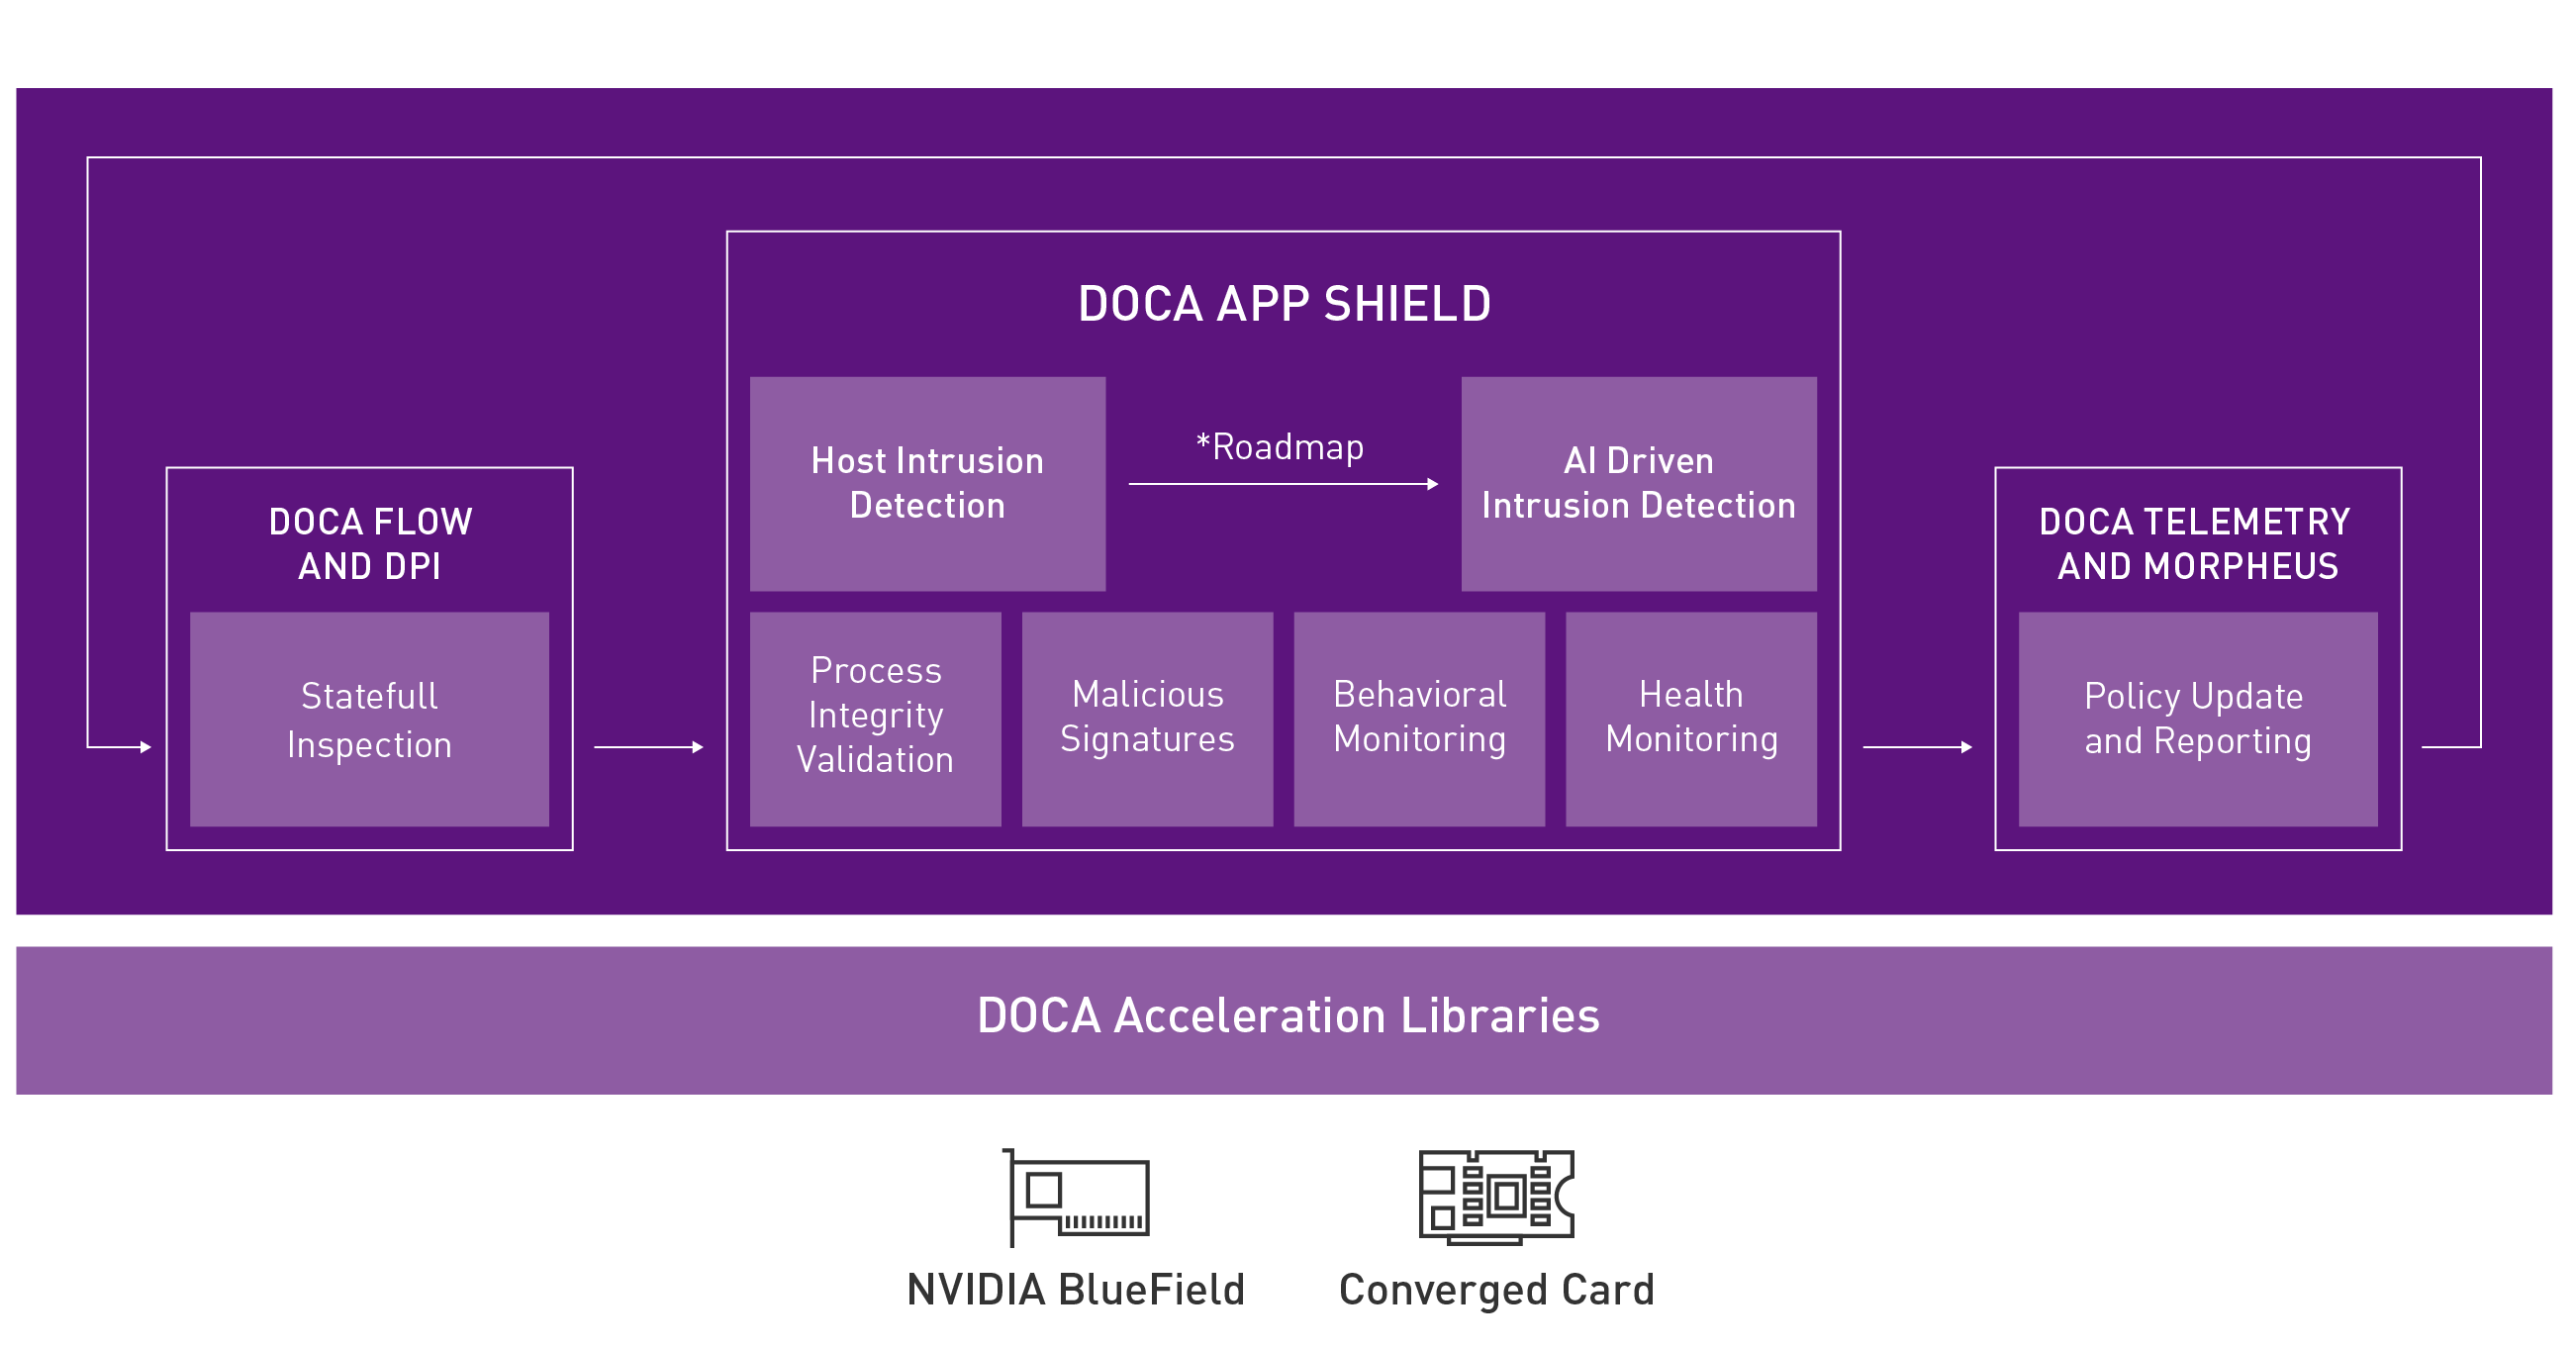
DOCA App Shield provides host monitoring enabling cybersecurity vendors to create accelerated intrusion detection system (IDS) solutions to identify an attack on any physical or virtual machine. It can feed data about application status to security information and event management (SIEM) or extended detection and response (XDR) tools and also enhances forensic investigations.
If a host is compromised, attackers normally exploit the security control mechanism breaches to move laterally across data center networks to other servers and devices. App Shield enables security teams to shield their application processes, continuously validate their integrity, and in turn detect malicious activity.
In the event that an attacker kills the machine security agent’s processes, App Shield can mitigate the attack by isolating the compromised host, preventing the malware from accessing confidential data or spreading to other resources. App Shield is an important advancement in the fight against cybercrime and an effective tool to enable a zero-trust security stance.
BlueField DPUs and the DOCA software framework provide an open foundation for partners and developers to build zero-trust solutions and address the security needs of the modern data center. Together, DOCA and BlueField create an isolated and secure services domain for networking, security, storage, and infrastructure management that is ideal for enabling a zero-trust strategy.
Precision timing is a critical capability to enable and accelerate distributed apps from edge to core. DOCA Firefly is a data center timing service that supports extremely precise time synchronization everywhere. With nanosecond-level clock synchronization, you can enable a new broad range of timing-critical and delay-sensitive applications.
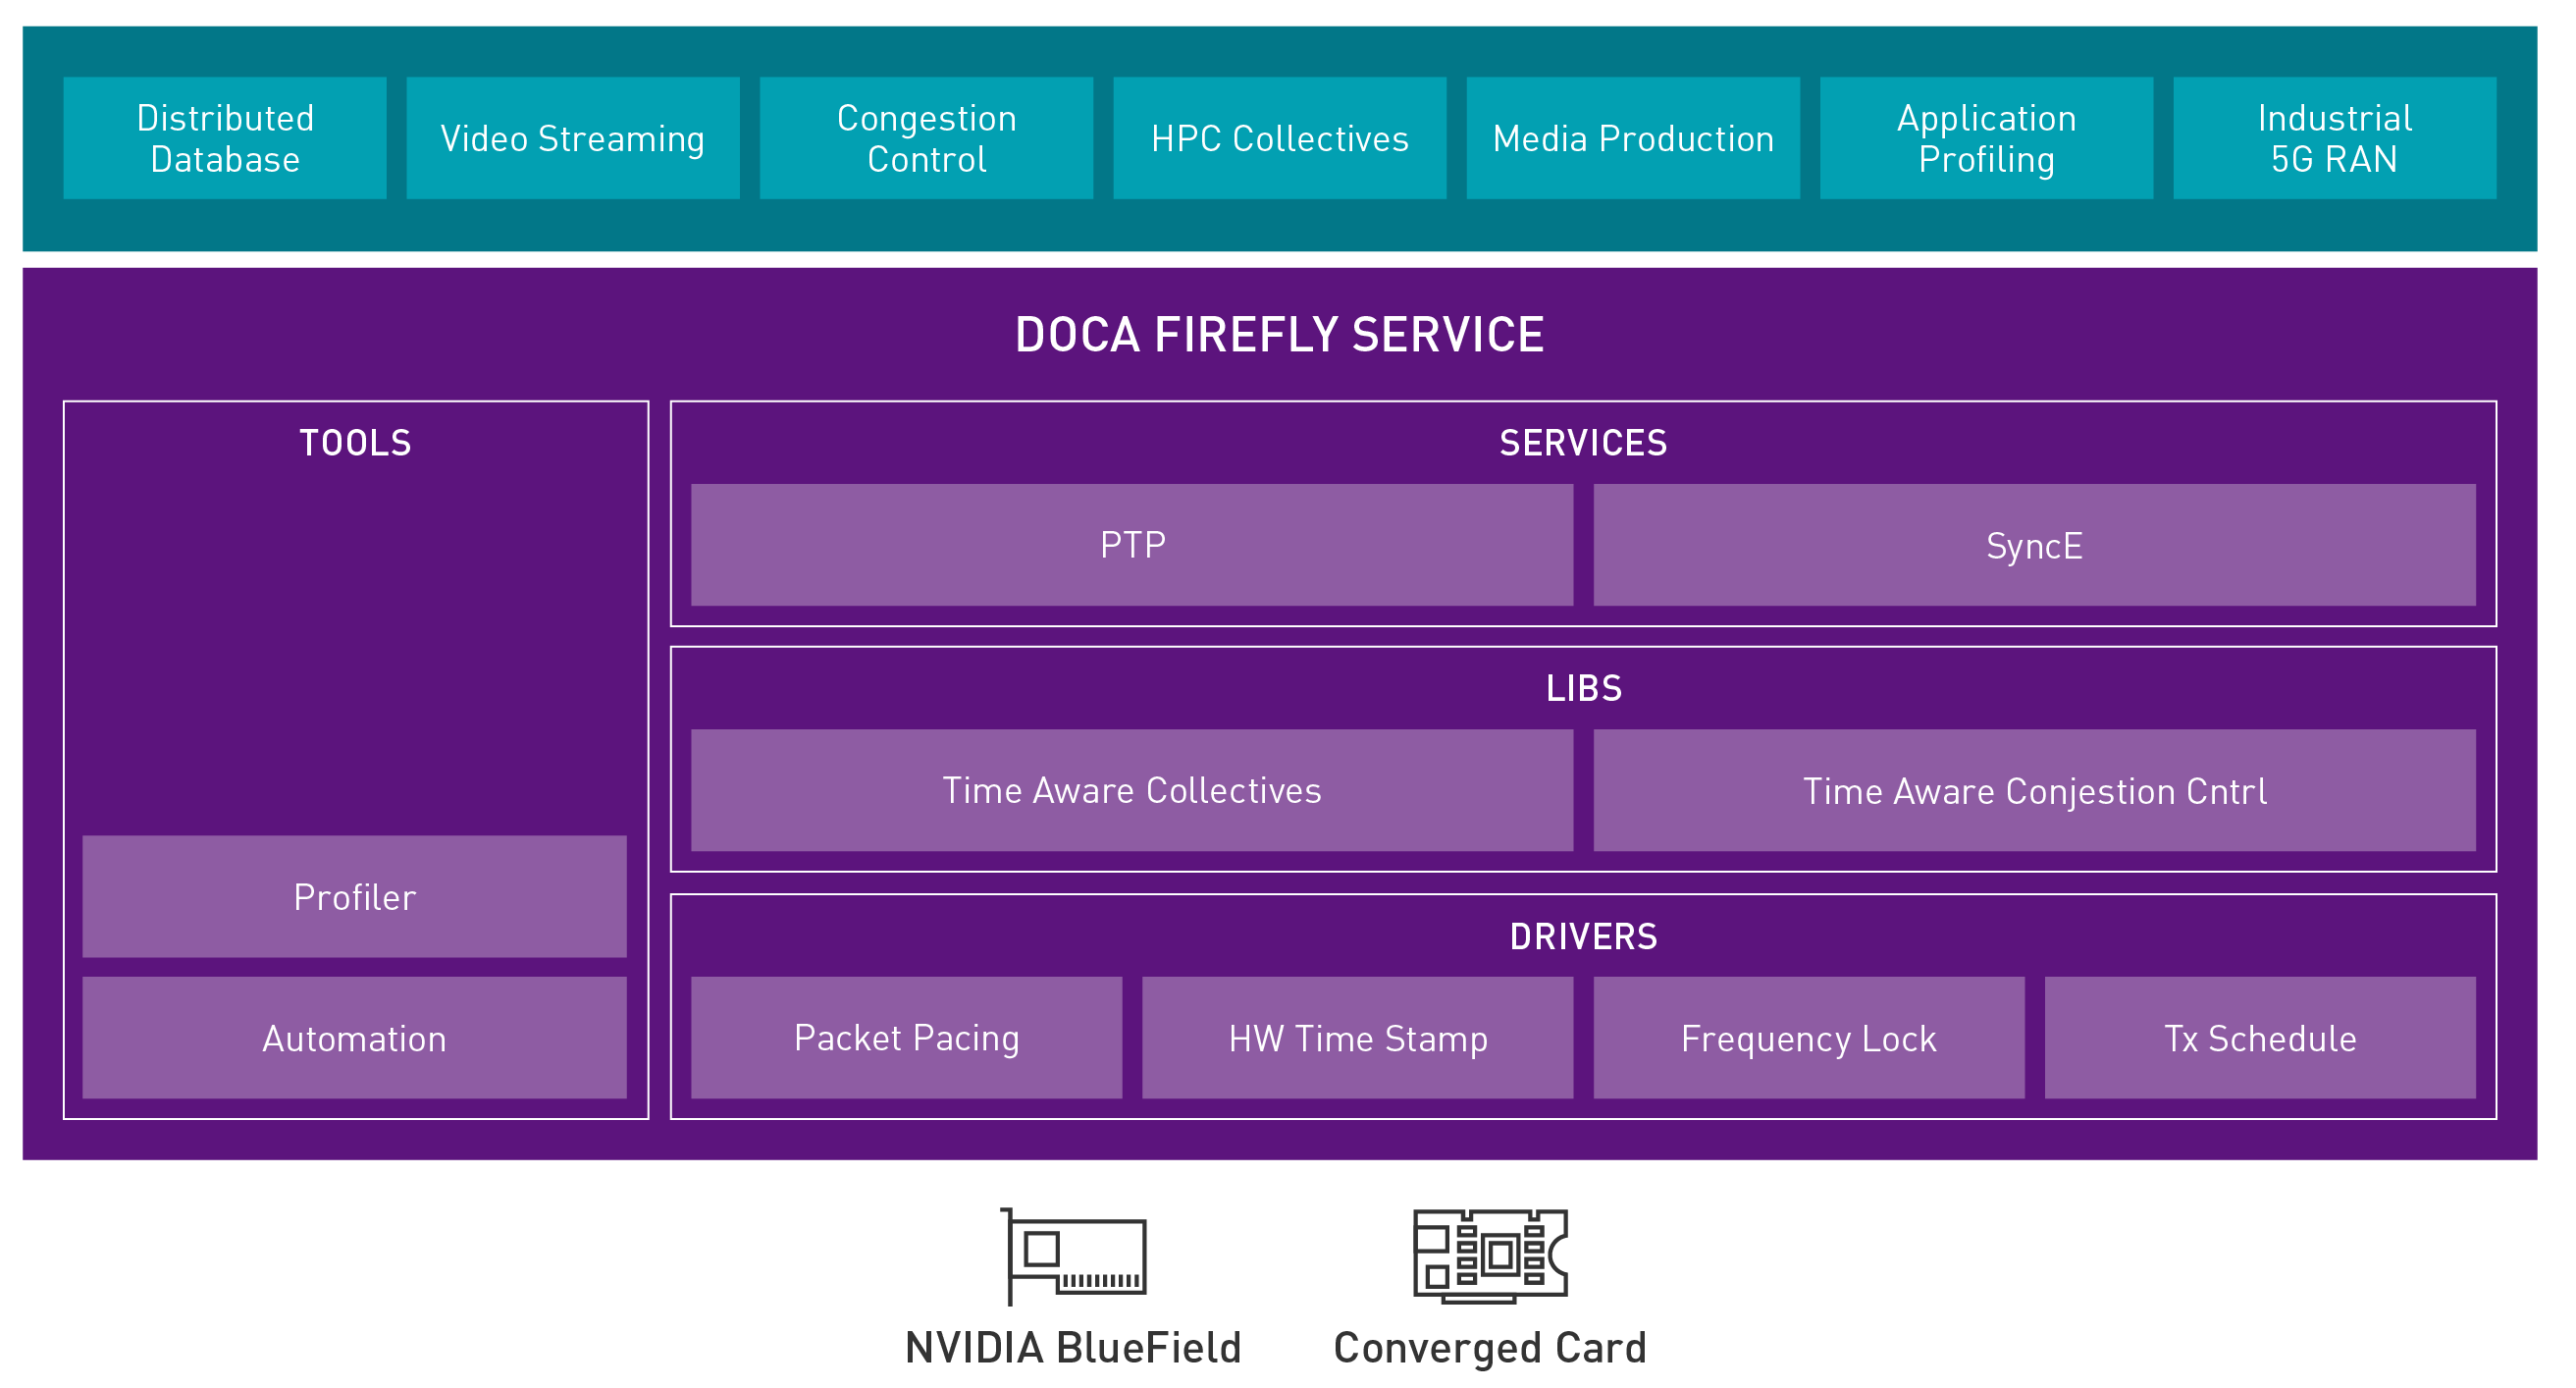
DOCA Firefly addresses a wide range of use cases, including the following:
It enables data consistency, accurate event ordering, and causality analysis, such as ensuring the correct sequencing of stock market transactions and fair bidding during digital auctions. The hardware engines in the BlueField application-specific integrated circuit (ASIC) are capable of time-stamping data packets at full wire speed with breakthrough nanosecond-level accuracy.
Improving the accuracy of data center timing by orders of magnitude offers many advantages.
With globally synchronized data centers, you can accelerate distributed applications and data analysis including AI, HPC, professional media production, telco virtual network functions, and precise event monitoring. All the servers in the data center—or across data centers—can be harmonized to provide something that is far bigger than any single compute node.
The benefits of improving data center timing accuracy include a reduction in the amount of compute power and network traffic needed to replicate and validate the data. For example, Firefly synchronization delivers a 3x database performance gain to distributed databases.
The BlueField DPU is a unique solution for network acceleration and policy enforcement within an endpoint host. At the same time, BlueField provides an administrative and software demarcation between the host operating system and functions running on the DPU.
With DOCA host-based networking (HBN), top-of-rack (TOR) network configuration can extend down to the DPU, enabling network administrators to own DPU configuration and management while application management can be handled separately by x86 host administrators. This creates an unparalleled opportunity to reimagine how you can build data center networks.
DOCA 1.2 provides a new driver for HBN called Netlink to DOCA (nl2doca) that accelerates and offloads traditional Linux Netlink messages. nl2doca is provided as an acceleration driver integrated as part of the HBN service container. You can now accelerate host networking for L2 and L3 that relies on DPDK, OVS, or now kernel routing with Netlink.
NVIDIA is adding support for the open-source Free Range Routing (FRR) project, running on the DPU and leveraging this new nl2doca driver. This support enables the DPU to operate exactly like a TOR switch plus additional benefits. FRR on the DPU enables EVPN networks to move directly into the host, providing layer 2 (VLAN) extension and layer 3 (VRF) tenant isolation.
HBN on the DPU can manage and monitor traffic between VMs or containers on the same node. It can also analyze and encrypt or decrypt then analyze traffic to and from the node, both tasks that no ToR switch can perform. You can build your own Amazon VPC-like solution in your private cloud for containerized, virtual machine, and bare metal workloads.
HBN with BlueField DPUs revolutionizes how you build data center networks. It offers the following benefits:
nl2doca driver provided by HBN enables any netlink capable application to offload and accelerate kernel based networking without the complexities of traditional DPDK libraries. Additional DOCA 1.2 SDK updates:
In addition, NVIDIA is introducing a Deep Learning Institute (DLI) course: Introduction to DOCA for the BlueField DPU. The main objective of this course is to provide students, including developers, researchers, and system administrators, with an introduction to DOCA and BlueField DPUs. This enables students to successfully work with DOCA to create accelerated applications and services powered by BlueField DPUs.
You can experience DOCA today with the DOCA software, which includes DOCA SDK and runtime accelerated libraries for networking, storage, and security. The libraries help you program your data center infrastructure running on the DPU.
The DOCA Early Access program is open now for applications. To receive news and updates about DOCA or to become an early access member/partner, register on the DOCA Early Access page.
For more information, see the following resources:
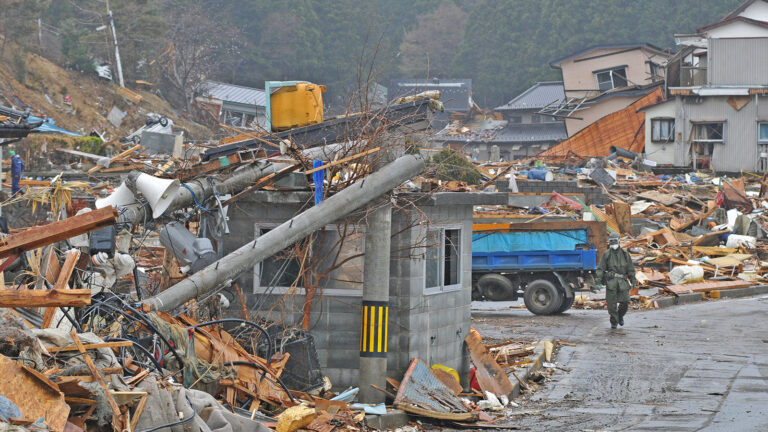 Researchers create a neural network that automatically detects tectonic fault deformation, crucial to understanding and possibly predicting earthquake behavior.
Researchers at Los Alamos National Laboratory in New Mexico are working toward earthquake detection with a new machine learning algorithm capable of global monitoring. The study uses Interferometric Synthetic Aperture Radar (InSAR) satellite data to detect slow-slip earthquakes. The work will help scientists gain a deeper understanding of the interplay between slow and fast earthquakes, which could be key to making future predictions of quake events.
“Applying machine learning to InSAR data gives us a new way to understand the physics behind tectonic faults and earthquakes,” Bertrand Rouet-Leduc, a geophysicist in Los Alamos’ Geophysics group said in a press release. “That’s crucial to understanding the full spectrum of earthquake behavior.”
Discovered a couple of decades ago, slow earthquakes remain a bit of a mystery. They occur at the boundary between plates and can last from days to months without detection due to their slow and quiet nature.
They typically happen in areas where faults are locked due to frictional resistance, and scientists believe they may precede major fast quakes. Japan’s 9.0 magnitude earthquake in 2011, which also caused a tsunami and the Fukushima nuclear disaster, followed two slow earthquakes along the Japan Trench.
Scientists can track earthquake behavior with InSAR satellite data. The radar waves have the benefit of penetrating clouds and also work effectively at night, making it possible to track ground deformation continuously. Comparing radar images over time, researchers can detect ground surface movement.
But these movements are small, and existing approaches limit ground deformation measurements to a few centimeters. Ongoing monitoring of global fault systems also creates massive data streams that are too much to interpret manually.
The researchers created deep learning models addressing both of these limitations. The team trained convolutional neural networks on several million time series of synthetic InSAR data to detect automatically and extract ground deformation.
Using cuDNN-accelerated TensorFlow deep learning framework distributed over multiple NVIDIA GPUs, the new methodology operates without prior knowledge of a fault’s location or slip behavior.
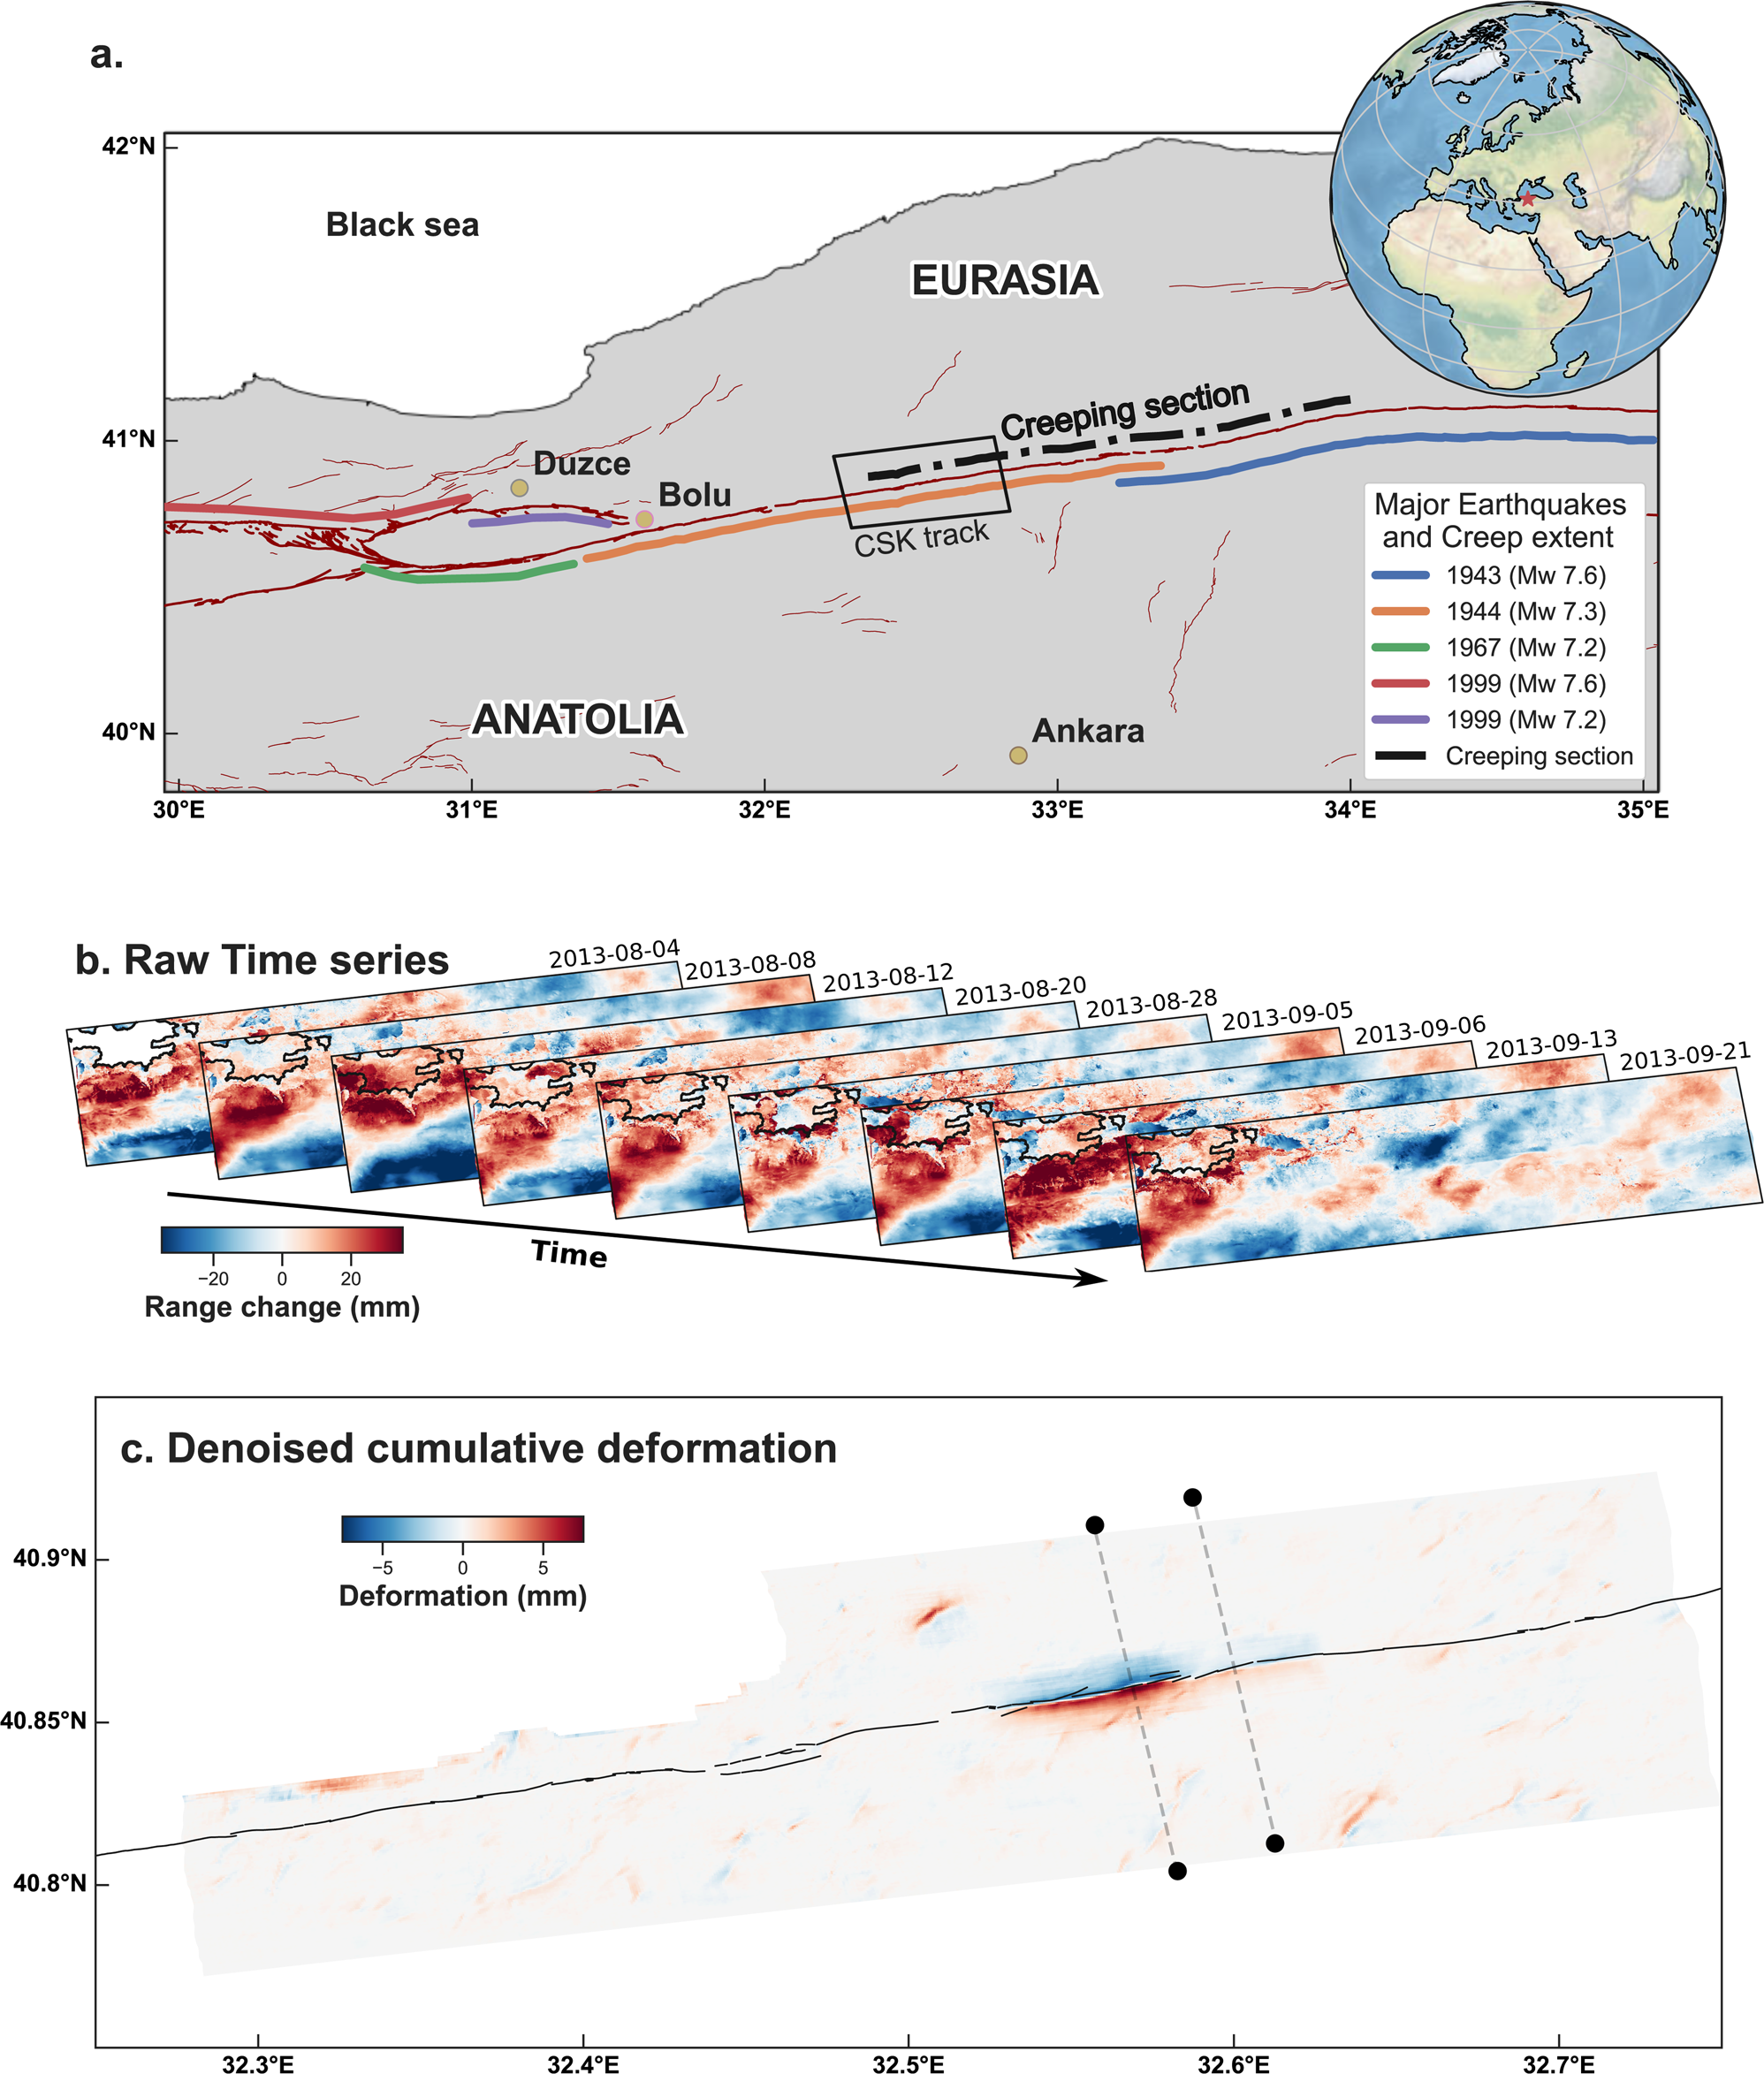
To test their approach, they applied the algorithm to a time series built from images of the North Anatolian fault in Turkey. As a major plate boundary fault, the area has ruptured several times in the past century.
With a finer temporal resolution, the algorithm identified previously undetected slippage events, showing that slow earthquakes happen much more often than expected. It also spotted movement as small as two millimeters, something experts would have overlooked due to the subtlety.
“The use of deep learning unlocks the detection on faults of deformation events an order of magnitude smaller than previously achieved manually. Observing many more slow slip events may, in turn, unveil their interaction with regular, dynamic earthquakes, including the potential nucleation of earthquakes with slow deformation,” Rouet-Leduc said.
The team is currently working on a follow-up study, testing a model on the San Andreas Fault that extends roughly 750 miles through California. According to Rouet-Leduc, the model will soon be available on GitHub.
Read the published research in Nature Communications. >>
Read the press release. >>
 Supply chain shortages are impacting many industries, with semiconductors feeling the crunch in particular. With networking digital twins, you don’t have to wait on the hardware. Get started with infrastructure simulation in NVIDIA Air to stage deployments, test out tools, and enable hardware-free training.
What do Ethernet switches, sports cars, household appliances, and toilet paper have in common? If you read this blog’s title and have lived through the past year and a half, you probably know the answer. These are all products whose availability has been impacted by the materials shortages due to the global pandemic.
In some instances, the supply issues are more of an inconvenience–waiting a few extra months to get that new Corvette won’t be the end of the world. For other products (think toilet paper or a replacement freezer), the supply crunch was and is a big deal.
It is easy to see the impact on consumers, but enterprises feel the pain of long lead times too. Consider Ethernet switches: Ethernet switches build the networking fabric that ties together the data center. Ethernet switch shortages mean more than “rack A is unable to talk to rack B.” They mean decreased aggregate throughput, and increased load on existing infrastructure, leading to more downtime and unplanned outages; that is, significant adverse impacts to business outcomes.
That all sounds bad, but there is no need to panic. NVIDIA can help you mitigate these challenges and transform your operations with a data center digital twin from NVIDIA Air.
So, what is a digital twin, and how is it related to the data center? A digital twin is a software-simulated replica of a real-world thing, system, or process. It constantly reacts and updates any changes to the status of its physical sibling and is always on. A data center digital twin applies the digital twin concept to data center infrastructure. To model the data center itself as a data center and not just a bunch of disparate pizza boxes, it is imperative that the data center digital twin fully simulates the network.
NVIDIA Air is unmatched in providing that capability. The modeling tool in Air enables you to create logical instances of every switch and cable, connecting to logical server instances. In addition to modeling the hardware, NVIDIA Air spins up fully functional virtual appliances with pre-built and fully functional network and server OS images. This is the key ingredient to the digital twin–with an appliance model, the simulation is application-granular.
NVIDIA Air enables data center digital twins, but how does that solve supply chain issues? Focusing on those benefits tied to hardware, in particular, it enables:
One caveat: data center digital twins will not expedite the date that the RTX 3090 comes back in stock at your favorite retailer, but they will help with the crunch around your networking procurement.
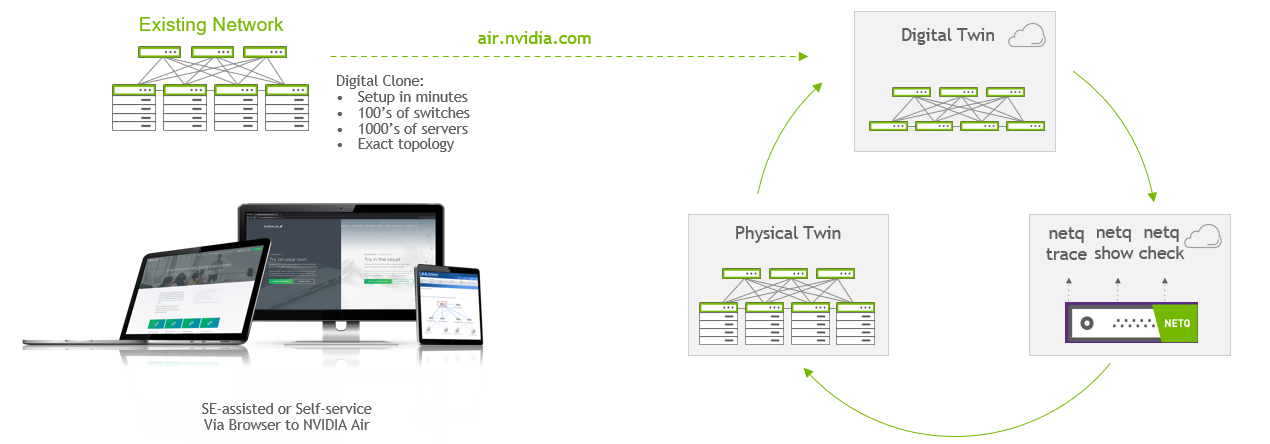
The best part – if you are curious to learn more, you can do so right now. NVIDIA Air brings the public cloud experience to on-premises networking, making it simple and quick to jump right in. Navigate to NVIDIA Air in your browser and get started immediately.
|
submitted by /u/alphapeeler [visit reddit] [comments] |
Hello! I’m a long time developer but new to AI-based image processing. The end goal is to process images from cameras and alert when deer (and eventually other wildlife) is detected.
The first step is finding a decent model that can (say) detect deer vs. birds vs. other animals, then running that somewhere. The default The CameraTraps model here allows detecting “animal” vs. “person” vs. “vehicle”:
https://github.com/microsoft/CameraTraps/blob/master/megadetector.md
Would I need to train it further to differentiate between types of animals, or am I missing something with the default model? Or a more general question, how can you see what a frozen model is set up to detect? (I just learned what a frozen model was yesterday)
Appreciate any pointers or if there’s another sub that would be more suited to getting this project setup, happy to post there instead 🙂
submitted by /u/brianhogg
[visit reddit] [comments]
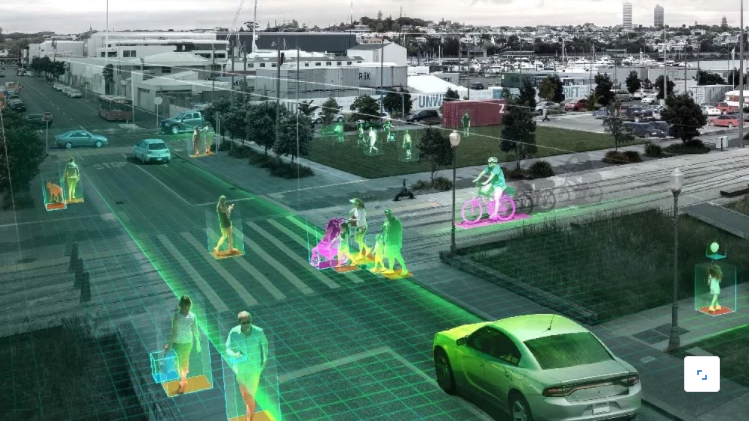 Explore NVIDIA Metropolis partners showcasing new technologies to improve city mobility at the ITS America 2021.
The Intelligent Transportation Society (ITS) of America annual conference brings together a community of intelligent transportation professionals to network, educate others about emerging technologies, and demonstrate innovative products driving the future of efficient and safe transportation.
As cities and DOT teams struggle with constrained roadway infrastructure and the need to build safer roads, events like this offer solutions and reveal a peek into the future. The NVIDIA Metropolis video analytics platform is increasingly being used by cities, DOTs, tollways, and developers to help measure, automate, and vastly improve the efficiency and safety of roadways around the world.
The following NVIDIA Metropolis partners are participating at ITS-America and showcasing how they help cities improve livability and safety.
Miovision: Arguably one of the first in building superhuman levels of computer vision into intersections, Miovison will explain how their technology is transforming traffic intersections, giving cities and towns more effective tools to manage traffic congestion, improving traffic safety, and reducing the impact of traffic on greenhouse gas emissions. Check out Miovision at booth #1619.
NoTraffic: NoTraffic’s real-time, plug-and-play autonomous traffic management platform uses AI and cloud computing to reinvent how cities run their transport networks. The NoTraffic platform is an end-to-end hardware and software solution installed at intersections, transforming roadways to optimize traffic flows and reduce accidents. Check out NoTraffic at booth #1001.
Ouster: Cities are using Ouster digital lidar solutions capable of capturing the environment in minute detail and detecting vehicles, vulnerable road users, and traffic incidents in real time to improve safety and traffic efficiency. Ouster lidar’s 3D spatial awareness and 24/7 performance combine the high-resolution imagery of cameras with the all-weather reliability of radar. Check out Ouster and a live demo at booth #2012.
Parsons: Parsons is a leading technology firm driving the future of smart infrastructure. Parsons develops advanced traffic management systems that cities use to improve safety, mobility, and livability. Check out Parsons at booth #1818.
Velodyne Lidar: Velodyne’s lidar-based Intelligent Infrastructure Solution (IIS) is a complete end-to-end Smart City solution. IIS creates a real-time 3D map of roads and intersections, providing precise traffic and pedestrian safety analytics, road user classification, and smart signal actuation. The solution is deployed in the US, Canada and across EMEA and APAC. Learn more about Velodyne’s on-the-ground deployments at their panel talk.
Register for ITS America, happening December 7-10 in Charlotte, NC.