Hey, I have trained multi out model in colab the model branch one will classify an image using passion loss the other branch will segment using binary crossentropy loss and using dicecoef as accuracy , when trained on colab the model gives good result accuracy:99,dicecoef:90
however when trained on my local machine one of two usually accurcuy randomly go to zero , nothing has changed used same code , same data only difference is I used tensorflow 2.5 while on colab it was 2.6.
I appoliges for the dirty codeing.
import os
os.environ[‘TF_CPP_MIN_LOG_LEVEL’] = ‘3’ # or any {‘0’, ‘1’, ‘2’}
import tensorflow as tf
import random
import numpy as np
import matplotlib.pyplot as plt
from tqdm import tqdm
from skimage.io import imread , imshow
from skimage.transform import resize
# example of pixel normalization
from numpy import asarray
# load image
import shutil
#import cv2 as cv
import tensorflow.keras.backend as K
from tensorflow.keras.losses import binary_crossentropy
beta = 0.25
alpha = 0.25
gamma = 2
epsilon = 1e-5
smooth = 1
class Semantic_loss_functions(object):
def __init__(self):
print (“semantic loss functions initialized”)
def dice_coef(self, y_true, y_pred):
y_true_f = K.flatten(y_true)
y_pred_f = K.flatten(y_pred)
intersection = K.sum(y_true_f * y_pred_f)
return (2. * intersection + K.epsilon()) / (
K.sum(y_true_f) + K.sum(y_pred_f) + K.epsilon())
def sensitivity(self, y_true, y_pred):
true_positives = K.sum(K.round(K.clip(y_true * y_pred, 0, 1)))
possible_positives = K.sum(K.round(K.clip(y_true, 0, 1)))
return true_positives / (possible_positives + K.epsilon())
def specificity(self, y_true, y_pred):
true_negatives = K.sum(
K.round(K.clip((1 – y_true) * (1 – y_pred), 0, 1)))
possible_negatives = K.sum(K.round(K.clip(1 – y_true, 0, 1)))
return true_negatives / (possible_negatives + K.epsilon())
def convert_to_logits(self, y_pred):
y_pred = tf.clip_by_value(y_pred, tf.keras.backend.epsilon(),
1 – tf.keras.backend.epsilon())
return tf.math.log(y_pred / (1 – y_pred))
def weighted_cross_entropyloss(self, y_true, y_pred):
y_pred = self.convert_to_logits(y_pred)
pos_weight = beta / (1 – beta)
loss = tf.nn.weighted_cross_entropy_with_logits(logits=y_pred,
targets=y_true,
pos_weight=pos_weight)
return tf.reduce_mean(loss)
def focal_loss_with_logits(self, logits, targets, alpha, gamma, y_pred):
weight_a = alpha * (1 – y_pred) ** gamma * targets
weight_b = (1 – alpha) * y_pred ** gamma * (1 – targets)
return (tf.math.log1p(tf.exp(-tf.abs(logits))) + tf.nn.relu(
-logits)) * (weight_a + weight_b) + logits * weight_b
def focal_loss(self, y_true, y_pred):
y_pred = tf.clip_by_value(y_pred, tf.keras.backend.epsilon(),
1 – tf.keras.backend.epsilon())
logits = tf.math.log(y_pred / (1 – y_pred))
loss = self.focal_loss_with_logits(logits=logits, targets=y_true,
alpha=alpha, gamma=gamma, y_pred=y_pred)
return tf.reduce_mean(loss)
def depth_softmax(self, matrix):
sigmoid = lambda x: 1 / (1 + K.exp(-x))
sigmoided_matrix = sigmoid(matrix)
softmax_matrix = sigmoided_matrix / K.sum(sigmoided_matrix, axis=0)
return softmax_matrix
def generalized_dice_coefficient(self, y_true, y_pred):
smooth = 1.
y_true_f = K.flatten(y_true)
y_pred_f = K.flatten(y_pred)
intersection = K.sum(y_true_f * y_pred_f)
score = (2. * intersection + smooth) / (
K.sum(y_true_f) + K.sum(y_pred_f) + smooth)
return score
def dice_loss(self, y_true, y_pred):
loss = 1 – self.generalized_dice_coefficient(y_true, y_pred)
return loss
def bce_dice_loss(self, y_true, y_pred):
loss = binary_crossentropy(y_true, y_pred) +
self.dice_loss(y_true, y_pred)
return loss / 2.0
def confusion(self, y_true, y_pred):
smooth = 1
y_pred_pos = K.clip(y_pred, 0, 1)
y_pred_neg = 1 – y_pred_pos
y_pos = K.clip(y_true, 0, 1)
y_neg = 1 – y_pos
tp = K.sum(y_pos * y_pred_pos)
fp = K.sum(y_neg * y_pred_pos)
fn = K.sum(y_pos * y_pred_neg)
prec = (tp + smooth) / (tp + fp + smooth)
recall = (tp + smooth) / (tp + fn + smooth)
return prec, recall
def true_positive(self, y_true, y_pred):
smooth = 1
y_pred_pos = K.round(K.clip(y_pred, 0, 1))
y_pos = K.round(K.clip(y_true, 0, 1))
tp = (K.sum(y_pos * y_pred_pos) + smooth) / (K.sum(y_pos) + smooth)
return tp
def true_negative(self, y_true, y_pred):
smooth = 1
y_pred_pos = K.round(K.clip(y_pred, 0, 1))
y_pred_neg = 1 – y_pred_pos
y_pos = K.round(K.clip(y_true, 0, 1))
y_neg = 1 – y_pos
tn = (K.sum(y_neg * y_pred_neg) + smooth) / (K.sum(y_neg) + smooth)
return tn
def tversky_index(self, y_true, y_pred):
y_true_pos = K.flatten(y_true)
y_pred_pos = K.flatten(y_pred)
true_pos = K.sum(y_true_pos * y_pred_pos)
false_neg = K.sum(y_true_pos * (1 – y_pred_pos))
false_pos = K.sum((1 – y_true_pos) * y_pred_pos)
alpha = 0.7
return (true_pos + smooth) / (true_pos + alpha * false_neg + (
1 – alpha) * false_pos + smooth)
def tversky_loss(self, y_true, y_pred):
return 1 – self.tversky_index(y_true, y_pred)
def focal_tversky(self, y_true, y_pred):
pt_1 = self.tversky_index(y_true, y_pred)
gamma = 0.75
return K.pow((1 – pt_1), gamma)
def log_cosh_dice_loss(self, y_true, y_pred):
x = self.dice_loss(y_true, y_pred)
return tf.math.log((tf.exp(x) + tf.exp(-x)) / 2.0)
########
n_filters=50
epochs=50
batch_size=6
Img_wedth =128
Img_height = 128
Img_channels = 1
#####################################
import h5py
paths=os.listdir(‘C:/Users/ASUS/Desktop/imageData/’)
## save images in arrays ##
X_train = np.zeros((len(paths) , Img_height , Img_wedth , Img_channels) , dtype = np.float32)
y_train = np.zeros((len(paths) , Img_height , Img_wedth , Img_channels ) , dtype = np.float32)
y_train_label=[]
#####################################
for n, id_ in tqdm(enumerate(paths) , total = len(paths)) :
ttt=[0,0,0]
path = ‘C:/Users/ASUS/Desktop/imageData/’+id_
#print(‘path.. ‘,path)
#print(‘id.. ‘,id_)
#img = imread(path + ‘/image/’ +id_ + ‘.png’) [: , : ]
img1=h5py.File(path,’r’)
# print(‘path.. ‘,path)
img=img1[‘cjdata’][‘image’]
img = resize(img , (Img_height , Img_wedth , Img_channels) , mode = ‘constant’ , preserve_range=True)
#print(img.shape)
# imshow(img,cmap=”gray”)
# plt.show()
img = asarray(img)
img = img.astype(‘float32’)
# normalize to the range 0-1
img = tf.image.per_image_standardization(img)
# print(img[55][55])
#print(img.shape)
X_train[n] = img
# print(‘path.. ‘,path)
mask=img1[‘cjdata’][‘tumorMask’]
mask = asarray(mask)
mask = mask.astype(‘float32’)
#_,mask=cv.threshold(mask, 0.01, 1, 0 )
mask = resize(mask , (Img_height , Img_wedth , Img_channels) , mode = ‘constant’ , preserve_range=True)
#print(img.shape)
# imshow(img,cmap=”gray”)
# plt.show()
# normalize to the range 0-1
ttt[int(img1[‘cjdata’][‘label’][0][0])-1]=img1[‘cjdata’][‘label’][0][0]
y_train_label.append(ttt)
y_train[n] = mask
# print(Mask_[55][55])
# Mask_ = np.expand_dims(resize(Mask_ , (Img_height , Img_wedth) , mode = ‘constant’ ,
# preserve_range = True) , axis = -1)
# Mask = np.maximum(Mask , Mask_ )
# Mask = np.zeros((Img_height , Img_wedth , 1) , dtype = np.bool)
y_train_label=np.array(y_train_label)
paths_test=os.listdir(‘C:/Users/ASUS/Desktop/test’)[10:20]
X_test = np.zeros((len(paths_test) , Img_height , Img_wedth , Img_channels ) , dtype = np.float32)
y_test = np.zeros((len(paths_test) , Img_height , Img_wedth , Img_channels ) , dtype = np.float32)
y_test_label= []
print(‘resizing test images’)
for n, id_ in tqdm(enumerate(paths_test) , total = len(paths_test)) :
path = ‘C:/Users/ASUS/Desktop/test/’+id_
ttt1=[0,0,0]
img1=h5py.File(path,’r’)
# print(‘path.. ‘,path)
img=img1[‘cjdata’][‘image’]
img = resize(img , (Img_height , Img_wedth , Img_channels) , mode = ‘constant’ , preserve_range=True)
#print(img.shape)
# imshow(img,cmap=”gray”)
# plt.show()
img = asarray(img)
img = img.astype(‘float32’)
img = tf.image.per_image_standardization(img)
# normalize to the range 0-1
X_test[n]=img
mask=h5py.File(path,’r’)
# print(‘path.. ‘,path)
mask1=mask[‘cjdata’][‘tumorMask’]
mask1 = asarray(mask1)
mask1 = mask1.astype(‘float32’)
# _,mask1=cv.threshold(mask1, 0.01, 1, 0 )
mask1 = resize(mask1 , (Img_height , Img_wedth , Img_channels) , mode = ‘constant’ , preserve_range=True)
#print(img.shape)
# imshow(img,cmap=”gray”)
# plt.show()
# normalize to the range 0-1
ttt1[int(img1[‘cjdata’][‘label’][0][0])-1]=img1[‘cjdata’][‘label’][0][0]
y_test_label.append(ttt1)
y_test[n]=mask1
#print(‘imagetestid..’,n,’imagetestname’,id_)
#imshow(img)
#plt.show()
#image_x = random.randint(0 , len(Train_ids))
#imshow(X_train[image_x])
#plt.show()
#imshow(np.squeeze( y_train[image_x]))
#plt.show()
## U-net Moudel
inputs = tf.keras.Input((Img_wedth , Img_height , Img_channels ))
c1 = tf.keras.layers.Conv2D(n_filters*1 , (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(inputs)
c1 = tf.keras.layers.Dropout(0.1 )(c1)
p1 = tf.keras.layers.MaxPooling2D((2,2 ))(c1)
print (‘Done_c1’)
c2 = tf.keras.layers.Conv2D(n_filters*2 , (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(p1)
c2 = tf.keras.layers.Dropout(0.1 )(c2)
p2 = tf.keras.layers.MaxPooling2D((2,2 ))(c2)
print (‘Done_c2’)
c3 = tf.keras.layers.Conv2D(n_filters*4 , (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(p2)
c3 = tf.keras.layers.Dropout(0.2 )(c3)
p3 = tf.keras.layers.MaxPooling2D((2,2 ))(c3)
print (‘Done_c3’)
c4 = tf.keras.layers.Conv2D(n_filters*8 , (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(p3)
c4 = tf.keras.layers.Dropout(0.2 )(c4)
p4 = tf.keras.layers.MaxPooling2D(pool_size=((2,2 )))(c4)
print (‘Done_c4’)
c5 = tf.keras.layers.Conv2D(n_filters*16 , (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(p4)
c5 = tf.keras.layers.Dropout(0.3 )(c5)
c5 = tf.keras.layers.Conv2D(n_filters*16, (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(c5)
print (‘Done_c5’)
F1=tf.keras.layers.Flatten()(c5)
D1=tf.keras.layers.Dense(32,activation=’relu’)(F1)
D2=tf.keras.layers.Dense(3,activation=’softmax’,name=’clas’)(D1)
u6 = tf.keras.layers.Conv2DTranspose(n_filters*8 , (2,2) , strides=(2,2) , padding=’same’)(c5)
print (‘Done_c61’)
u6 = tf.keras.layers.Concatenate(axis=-1)([u6 , c4])
print (‘Done_c62’)
c6 = tf.keras.layers.Conv2D(n_filters*8 ,(3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(u6)
print (‘Done_c63’)
c6 = tf.keras.layers.Dropout(0.2 )(c6)
c6 = tf.keras.layers.Conv2D(n_filters*8, (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(c6)
print (‘Done_c6’)
u7 = tf.keras.layers.Conv2DTranspose(n_filters*4 , (2,2) , strides=(2,2) , padding=’same’)(c6)
u7 = tf.keras.layers.Concatenate(axis=-1)([u7 , c3])
c7 = tf.keras.layers.Conv2D(n_filters*4 , (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(u7)
c7 = tf.keras.layers.Dropout(0.2 )(c7)
c7 = tf.keras.layers.Conv2D(n_filters*4 , (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(c7)
print (‘Done_c7’)
u8 = tf.keras.layers.Conv2DTranspose(n_filters*2 , (2,2) , strides=(2,2) , padding=’same’)(c7)
u8 = tf.keras.layers.Concatenate(axis=-1)([u8 , c2])
c8 = tf.keras.layers.Conv2D(n_filters*2 , (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(u8)
c8 = tf.keras.layers.Dropout(0.2)(c8)
c8 = tf.keras.layers.Conv2D(n_filters*2 , (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(c8)
print (‘Done_c8’)
u9 = tf.keras.layers.Conv2DTranspose(n_filters*1 , (2,2) , strides=(2,2) , padding=’same’)(c8)
print (‘Done_c91’)
u9 = tf.keras.layers.Concatenate(axis=-1)([u9 , c1])
print (‘Done_c92’)
c9 = tf.keras.layers.Conv2D(n_filters*1 , (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(u9)
print (‘Done_c93’)
c9 = tf.keras.layers.Dropout(0.4)(c9)
print (‘Done_c94’)
c9 = tf.keras.layers.Conv2D(n_filters*1 , (3,3) , activation=’relu’
, kernel_initializer=’he_normal’ , padding=’same’)(c9)
print (‘Done_c9’)
outputs = tf.keras.layers.Conv2D(1 , (1,1) , activation=’sigmoid’,name=’seg’)(c9)
print (‘Done_out’)
model = tf.keras.Model(inputs=[inputs] , outputs=[outputs,D2])
print (‘Done_model1’)
def dice_coef1(y_true, y_pred, smooth=1):
print(y_true.shape,y_pred.shape)
intersection = K.sum((y_true )*( tf.round(y_pred)), axis=[1,2,3])
union = K.sum((y_true), axis=[1,2,3]) + K.sum((tf.round(y_pred)), axis=[1,2,3])
dice = K.mean((2. * intersection + smooth)/(union + smooth), axis=0)
return dice
loss={“seg”:binary_crossentropy,
“clas”:tf.keras.losses.poisson}
metricss={‘seg’:dice_coef1,
‘clas’:’Accuracy’}
opt=tf.keras.optimizers.Adam(clipvalue=1,clipnorm=1,lr=0.0001)
s = Semantic_loss_functions()
model.compile(optimizer=opt, loss=loss, metrics=metricss)
model.summary()
#############
# modelchecpoints
from tensorflow.keras import callbacks
results = model.fit(X_train , [y_train,y_train_label] ,shuffle=True, batch_size =batch_size, epochs=epochs )

 This NVIDIA Inception Spotlight features Resemble AI, a new generative voice technology startup able to create high-quality synthetic AI voices.
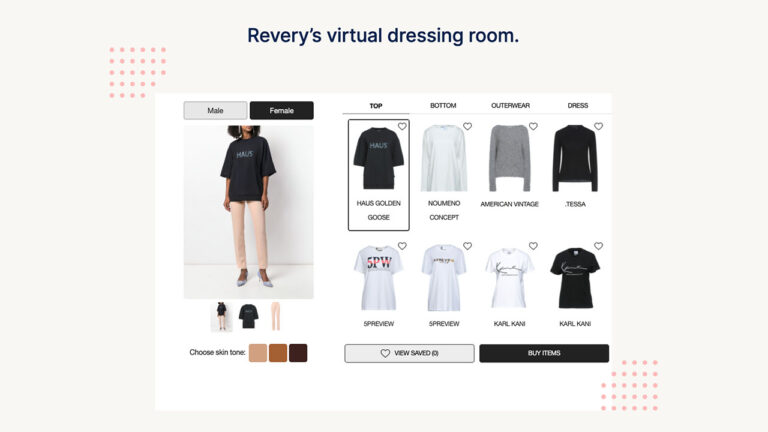 With the help of AI, a new fashion startup offers online retailers a scalable virtual dressing room, capable of cataloging over a million garment images weekly.