|
|
submitted by /u/1991viet [visit reddit] [comments] |
Categories
 DataBloom
|
|
|
submitted by /u/1991viet [visit reddit] [comments] |
Hi there! im very new at this so if i’ve left anything out please let me know!
so far ive downloaded the file, used cd to get into it and then have done this:
conda create -n py36 python=3.6 anaconda pip3 install tensorflow==1.12.0 pip3 install -r requirements.txt python3 download_model.py 124M
and upon running
python3 src/interactive_conditional_samples.py --top_k 40
Anaconda returns
C:ProgramDataAnaconda3envspy36libsite-packagestensorflowpythonframeworkdtypes.py:523: FutureWarning: Passing (type, 1) or '1type' as a synonym of type is deprecated; in a future version of numpy, it will be understood as (type, (1,)) / '(1,)type'. _np_qint8 = np.dtype([("qint8", np.int8, 1)]) C:ProgramDataAnaconda3envspy36libsite-packagestensorflowpythonframeworkdtypes.py:524: FutureWarning: Passing (type, 1) or '1type' as a synonym of type is deprecated; in a future version of numpy, it will be understood as (type, (1,)) / '(1,)type'. _np_quint8 = np.dtype([("quint8", np.uint8, 1)]) C:ProgramDataAnaconda3envspy36libsite-packagestensorflowpythonframeworkdtypes.py:525: FutureWarning: Passing (type, 1) or '1type' as a synonym of type is deprecated; in a future version of numpy, it will be understood as (type, (1,)) / '(1,)type'. _np_qint16 = np.dtype([("qint16", np.int16, 1)]) C:ProgramDataAnaconda3envspy36libsite-packagestensorflowpythonframeworkdtypes.py:526: FutureWarning: Passing (type, 1) or '1type' as a synonym of type is deprecated; in a future version of numpy, it will be understood as (type, (1,)) / '(1,)type'. _np_quint16 = np.dtype([("quint16", np.uint16, 1)]) C:ProgramDataAnaconda3envspy36libsite-packagestensorflowpythonframeworkdtypes.py:527: FutureWarning: Passing (type, 1) or '1type' as a synonym of type is deprecated; in a future version of numpy, it will be understood as (type, (1,)) / '(1,)type'. _np_qint32 = np.dtype([("qint32", np.int32, 1)]) C:ProgramDataAnaconda3envspy36libsite-packagestensorflowpythonframeworkdtypes.py:532: FutureWarning: Passing (type, 1) or '1type' as a synonym of type is deprecated; in a future version of numpy, it will be understood as (type, (1,)) / '(1,)type'. np_resource = np.dtype([("resource", np.ubyte, 1)]) 2021-03-15 16:39:25.892397: I tensorflow/core/platform/cpu_feature_guard.cc:141] Your CPU supports instructions that this TensorFlow binary was not compiled to use: AVX2 Traceback (most recent call last): File "src/interactive_conditional_samples.py", line 91, in <module> fire.Fire(interact_model) File "C:ProgramDataAnaconda3envspy36libsite-packagesfirecore.py", line 141, in Fire component_trace = _Fire(component, args, parsed_flag_args, context, name) File "C:ProgramDataAnaconda3envspy36libsite-packagesfirecore.py", line 471, in _Fire target=component.__name__) File "C:ProgramDataAnaconda3envspy36libsite-packagesfirecore.py", line 681, in _CallAndUpdateTrace component = fn(*varargs, **kwargs) File "src/interactive_conditional_samples.py", line 65, in interact_model temperature=temperature, top_k=top_k, top_p=top_p File "C:UserslouisOneDriveDesktopgpt-2-testsrcsample.py", line 74, in sample_sequence past, prev, output = body(None, context, context) File "C:UserslouisOneDriveDesktopgpt-2-testsrcsample.py", line 66, in body logits = top_p_logits(logits, p=top_p) File "C:UserslouisOneDriveDesktopgpt-2-testsrcsample.py", line 28, in top_p_logits sorted_logits = tf.sort(logits, direction='DESCENDING', axis=-1) AttributeError: module 'tensorflow' has no attribute 'sort'
I have no idea what any of this means. if someone could help me out it would mean a lot! 🙂
submitted by /u/LouisHendrich
[visit reddit] [comments]
|
|
|
submitted by /u/1991viet [visit reddit] [comments] |
Today, we continue our exploration of multi-step time-series forecasting with torch. This post is the third in a series.
Initially, we covered basics of recurrent neural networks (RNNs), and trained a model to predict the very next value in a sequence. We also found we could forecast quite a few steps ahead by feeding back individual predictions in a loop.
Next, we built a model “natively” for multi-step prediction. A small multi-layer-perceptron (MLP) was used to project RNN output to several time points in the future.
Of both approaches, the latter was the more successful. But conceptually, it has an unsatisfying touch to it: When the MLP extrapolates and generates output for, say, ten consecutive points in time, there is no causal relation between those. (Imagine a weather forecast for ten days that never got updated.)
Now, we’d like to try something more intuitively appealing. The input is a sequence; the output is a sequence. In natural language processing (NLP), this type of task is very common: It’s exactly the kind of situation we see with machine translation or summarization.
Quite fittingly, the types of models employed to these ends are named sequence-to-sequence models (often abbreviated seq2seq). In a nutshell, they split up the task into two components: an encoding and a decoding part. The former is done just once per input-target pair. The latter is done in a loop, as in our first try. But the decoder has more information at its disposal: At each iteration, its processing is based on the previous prediction as well as previous state. That previous state will be the encoder’s when a loop is started, and its own ever thereafter.
Before discussing the model in detail, we need to adapt our data input mechanism.
Data input
We continue working with vic_elec , provided by tsibbledata.
Again, the dataset definition in the current post looks a bit different from the way it did before; it’s the shape of the target that differs. This time, y equals x, shifted to the left by one.
The reason we do this is owed to the way we are going to train the network. With seq2seq, people often use a technique called “teacher forcing” where, instead of feeding back its own prediction into the decoder module, you pass it the value it should have predicted. To be clear, this is done during training only, and to a configurable degree.
n_timesteps <- 7 * 24 * 2
n_forecast <- n_timesteps

vic_elec_get_year <- function(year, month = NULL) {
  vic_elec %>%
    filter(year(Date) == year, month(Date) == if (is.null(month)) month(Date) else month) %>%
    as_tibble() %>%
    select(Demand)
}

elec_train <- vic_elec_get_year(2012) %>% as.matrix()
elec_valid <- vic_elec_get_year(2013) %>% as.matrix()
elec_test <- vic_elec_get_year(2014, 1) %>% as.matrix()

train_mean <- mean(elec_train)
train_sd <- sd(elec_train)

elec_dataset <- dataset(
  name = "elec_dataset",

  initialize = function(x, n_timesteps, sample_frac = 1) {

    self$n_timesteps <- n_timesteps
    self$x <- torch_tensor((x - train_mean) / train_sd)

    n <- length(self$x) - self$n_timesteps - 1

    self$starts <- sort(sample.int(
      n = n,
      size = n * sample_frac
    ))

  },

  .getitem = function(i) {

    start <- self$starts[i]
    end <- start + self$n_timesteps - 1
    lag <- 1

    list(
      x = self$x[start:end],
      y = self$x[(start+lag):(end+lag)]$squeeze(2)
    )

  },

  .length = function() {
    length(self$starts)
  }
)
Dataset as well as dataloader instantations then can proceed as before.
batch_size <- 32

train_ds <- elec_dataset(elec_train, n_timesteps, sample_frac = 0.5)
train_dl <- train_ds %>% dataloader(batch_size = batch_size, shuffle = TRUE)

valid_ds <- elec_dataset(elec_valid, n_timesteps, sample_frac = 0.5)
valid_dl <- valid_ds %>% dataloader(batch_size = batch_size)

test_ds <- elec_dataset(elec_test, n_timesteps)
test_dl <- test_ds %>% dataloader(batch_size = 1)
Model
Technically, the model consists of three modules: the aforementioned encoder and decoder, and the seq2seq module that orchestrates them.
Encoder
The encoder takes its input and runs it through an RNN. Of the two things returned by a recurrent neural network, outputs and state, so far we’ve only been using output. This time, we do the opposite: We throw away the outputs, and only return the state.
If the RNN in question is a GRU (and assuming that of the outputs, we take just the final time step, which is what we’ve been doing throughout), there really is no difference: The final state equals the final output. If it’s an LSTM, however, there is a second kind of state, the “cell state”. In that case, returning the state instead of the final output will carry more information.
encoder_module <- nn_module(

  initialize = function(type, input_size, hidden_size, num_layers = 1, dropout = 0) {

    self$type <- type

    self$rnn <- if (self$type == "gru") {
      nn_gru(
        input_size = input_size,
        hidden_size = hidden_size,
        num_layers = num_layers,
        dropout = dropout,
        batch_first = TRUE
      )
    } else {
      nn_lstm(
        input_size = input_size,
        hidden_size = hidden_size,
        num_layers = num_layers,
        dropout = dropout,
        batch_first = TRUE
      )
    }

  },

  forward = function(x) {

    x <- self$rnn(x)

    # return last states for all layers
    # per layer, a single tensor for GRU, a list of 2 tensors for LSTM
    x <- x[[2]]
    x

  }

)
Decoder
In the decoder, just like in the encoder, the main component is an RNN. In contrast to previously-shown architectures, though, it does not just return a prediction. It also reports back the RNN’s final state.
decoder_module <- nn_module(

  initialize = function(type, input_size, hidden_size, num_layers = 1) {

    self$type <- type

    self$rnn <- if (self$type == "gru") {
      nn_gru(
        input_size = input_size,
        hidden_size = hidden_size,
        num_layers = num_layers,
        batch_first = TRUE
      )
    } else {
      nn_lstm(
        input_size = input_size,
        hidden_size = hidden_size,
        num_layers = num_layers,
        batch_first = TRUE
      )
    }

    self$linear <- nn_linear(hidden_size, 1)

  },

  forward = function(x, state) {

    # input to forward:
    # x is (batch_size, 1, 1)
    # state is (1, batch_size, hidden_size)
    x <- self$rnn(x, state)

    # break up RNN return values
    # output is (batch_size, 1, hidden_size)
    # next_hidden is
    c(output, next_hidden) %<-% x

    output <- output$squeeze(2)
    output <- self$linear(output)

    list(output, next_hidden)

  }

)
seq2seq module
seq2seq is where the action happens. The plan is to encode once, then call the decoder in a loop.
If you look back to decoder forward(), you see that it takes two arguments: x and state.
Depending on the context, x corresponds to one of three things: final input, preceding prediction, or prior ground truth.
The very first time the decoder is called on an input sequence, x maps to the final input value. This is different from a task like machine translation, where you would pass in a start token. With time series, though, we’d like to continue where the actual measurements stop.
In further calls, we want the decoder to continue from its most recent prediction. It is only logical, thus, to pass back the preceding forecast.
That said, in NLP a technique called “teacher forcing” is commonly used to speed up training. With teacher forcing, instead of the forecast we pass the actual ground truth, the thing the decoder should have predicted. We do that only in a configurable fraction of cases, and – naturally – only while training. The rationale behind this technique is that without this form of re-calibration, consecutive prediction errors can quickly erase any remaining signal.
state, too, is polyvalent. But here, there are just two possibilities: encoder state and decoder state.
The first time the decoder is called, it is “seeded” with the final state from the encoder. Note how this is the only time we make use of the encoding.
From then on, the decoder’s own previous state will be passed. Remember how it returns two values, forecast and state?
seq2seq_module <- nn_module(

  initialize = function(type, input_size, hidden_size, n_forecast, num_layers = 1, encoder_dropout = 0) {

    self$encoder <- encoder_module(type = type, input_size = input_size,
                                   hidden_size = hidden_size, num_layers, encoder_dropout)
    self$decoder <- decoder_module(type = type, input_size = input_size,
                                   hidden_size = hidden_size, num_layers)
    self$n_forecast <- n_forecast

  },

  forward = function(x, y, teacher_forcing_ratio) {

    # prepare empty output
    outputs <- torch_zeros(dim(x)[1], self$n_forecast)$to(device = device)

    # encode current input sequence
    hidden <- self$encoder(x)

    # prime decoder with final input value and hidden state from the encoder
    out <- self$decoder(x[ , n_timesteps, , drop = FALSE], hidden)

    # decompose into predictions and decoder state
    # pred is (batch_size, 1)
    # state is (1, batch_size, hidden_size)
    c(pred, state) %<-% out

    # store first prediction
    outputs[ , 1] <- pred$squeeze(2)

    # iterate to generate remaining forecasts
    for (t in 2:self$n_forecast) {

      # call decoder on either ground truth or previous prediction, plus previous decoder state
      teacher_forcing <- runif(1) < teacher_forcing_ratio
      input <- if (teacher_forcing == TRUE) y[ , t - 1, drop = FALSE] else pred
      input <- input$unsqueeze(3)
      out <- self$decoder(input, state)

      # again, decompose decoder return values
      c(pred, state) %<-% out
      # and store current prediction
      outputs[ , t] <- pred$squeeze(2)
    }
    outputs
  }

)

net <- seq2seq_module("gru", input_size = 1, hidden_size = 32, n_forecast = n_forecast)

# training RNNs on the GPU currently prints a warning that may clutter
# the console
# see https://github.com/mlverse/torch/issues/461
# alternatively, use
# device <- "cpu"
device <- torch_device(if (cuda_is_available()) "cuda" else "cpu")

net <- net$to(device = device)
Training
The training procedure is mainly unchanged. We do, however, need to decide about teacher_forcing_ratio, the proportion of input sequences we want to perform re-calibration on. In valid_batch(), this should always be 0, while in train_batch(), it’s up to us (or rather, experimentation). Here, we set it to 0.3.
optimizer <- optim_adam(net$parameters, lr = 0.001)

num_epochs <- 50

train_batch <- function(b, teacher_forcing_ratio) {

  optimizer$zero_grad()
  output <- net(b$x$to(device = device), b$y$to(device = device), teacher_forcing_ratio)
  target <- b$y$to(device = device)

  loss <- nnf_mse_loss(output, target)
  loss$backward()
  optimizer$step()

  loss$item()

}

valid_batch <- function(b, teacher_forcing_ratio = 0) {

  output <- net(b$x$to(device = device), b$y$to(device = device), teacher_forcing_ratio)
  target <- b$y$to(device = device)

  loss <- nnf_mse_loss(output, target)

  loss$item()

}

for (epoch in 1:num_epochs) {

  net$train()
  train_loss <- c()

  coro::loop(for (b in train_dl) {
    loss <-train_batch(b, teacher_forcing_ratio = 0.3)
    train_loss <- c(train_loss, loss)
  })

  cat(sprintf("nEpoch %d, training: loss: %3.5f n", epoch, mean(train_loss)))

  net$eval()
  valid_loss <- c()

  coro::loop(for (b in valid_dl) {
    loss <- valid_batch(b)
    valid_loss <- c(valid_loss, loss)
  })

  cat(sprintf("nEpoch %d, validation: loss: %3.5f n", epoch, mean(valid_loss)))
}
Epoch 1, training: loss: 0.37961

Epoch 1, validation: loss: 1.10699

Epoch 2, training: loss: 0.19355

Epoch 2, validation: loss: 1.26462

# ...
# ...

Epoch 49, training: loss: 0.03233

Epoch 49, validation: loss: 0.62286

Epoch 50, training: loss: 0.03091

Epoch 50, validation: loss: 0.54457
It’s interesting to compare performances for different settings of teacher_forcing_ratio. With a setting of 0.5, training loss decreases a lot more slowly; the opposite is seen with a setting of 0. Validation loss, however, is not affected significantly.
Evaluation
The code to inspect test-set forecasts is unchanged.
net$eval()

test_preds <- vector(mode = "list", length = length(test_dl))

i <- 1

coro::loop(for (b in test_dl) {

  input <- b$x
  output <- net(input$to(device = device))
  preds <- as.numeric(output)

  test_preds[[i]] <- preds
  i <<- i + 1

})

vic_elec_jan_2014 <- vic_elec %>%
  filter(year(Date) == 2014, month(Date) == 1)

test_pred1 <- test_preds[[1]]
test_pred1 <- c(rep(NA, n_timesteps), test_pred1, rep(NA, nrow(vic_elec_jan_2014) - n_timesteps - n_forecast))

test_pred2 <- test_preds[[408]]
test_pred2 <- c(rep(NA, n_timesteps + 407), test_pred2, rep(NA, nrow(vic_elec_jan_2014) - 407 - n_timesteps - n_forecast))

test_pred3 <- test_preds[[817]]
test_pred3 <- c(rep(NA, nrow(vic_elec_jan_2014) - n_forecast), test_pred3)


preds_ts <- vic_elec_jan_2014 %>%
  select(Demand) %>%
  add_column(
    mlp_ex_1 = test_pred1 * train_sd + train_mean,
    mlp_ex_2 = test_pred2 * train_sd + train_mean,
    mlp_ex_3 = test_pred3 * train_sd + train_mean) %>%
  pivot_longer(-Time) %>%
  update_tsibble(key = name)


preds_ts %>%
  autoplot() +
  scale_colour_manual(values = c("#08c5d1", "#00353f", "#ffbf66", "#d46f4d")) +
  theme_minimal()

(#fig:unnamed-chunk-8)One-week-ahead predictions for January, 2014.
Comparing this to the forecast obtained from last time’s RNN-MLP combo, we don’t see much of a difference. Is this surprising? To me it is. If asked to speculate about the reason, I would probably say this: In all of the architectures we’ve used so far, the main carrier of information has been the final hidden state of the RNN (one and only RNN in the two previous setups, encoder RNN in this one). It will be interesting to see what happens in the last part of this series, when we augment the encoder-decoder architecture by attention.
Thanks for reading!
Photo by Suzuha Kozuki on Unsplash
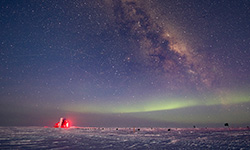 Scientists from the Wisconsin IceCube Particle Astrophysics Center are using ray tracing on NVIDIA GPUs to accelerate simulations of subatomic particles by hundreds of times.
Using NVIDIA RTX GPUs in a subsystem of the Texas Advanced Computing Center’s Frontera supercomputer, the researchers can calculate the path of light as it travels through a one cubic kilometer block of ice at Antarctica’s IceCube Neutrino Observatory.
They’re analyzing neutrinos, tiny particles created by cosmic rays that interact with Earth’s atmosphere. The ice block, located at the Amundsen-Scott South Pole Station, is rigged with sensors over a thousand feet under the surface, which transform signals from neutrino interactions into digital data.
“Based on the analysis, researchers are also able to determine where in the sky the particle came from, its energy, and sometimes, what type of neutrino — electron, muon or tau — it was,” said James Madson, executive director at IceCube.
The researchers are especially interested in neutrino events, or spikes in activity that can be traced to high-energy cosmic events billions of light years away. But these analyses require significant computational resources, making the IceCube team among the largest users of the Frontera GPU subsystem.
To better understand how neutrinos travel through the observatory’s ice block, the scientists use GPU-accelerated ray tracing to simulate how light propagates through the ice, tracking high-energy particles that are produced when neutrinos interact. Defects in the ice can cause the light to scatter or be absorbed, making it harder to analyze.
“Large scale simulations of the IceCube facility and the data it creates allow us to rapidly and accurately determine the properties of these neutrinos, which in turn exposes the physics of the most energetic events in the universe,” said Niall Gaffney, director of data intensive computing at the Texas Advanced Computing Center. “This is key to validating the fundamental quantum-mechanical physics in environments that cannot be practically replicated on earth.”
Read more from the Texas Advanced Computing Center >>
|
submitted by /u/Noe_Achache [visit reddit] [comments] |
TL/DR: Teaching myself about investing and Tensorflow. My model predicts Coca Cola will close $51.35 on 3/19/2021. I have no idea what I’m doing. Do not use this to make financial decisions.
So last week I predicted Coca Cola would close at $42.56. It really closed at $50.36. I would have been better off using the lazy predictor and just assume last week’s close of $50.79 would not have moved. See my previous post:
https://www.reddit.com/r/tensorflow/comments/lzv277/silly_prediction_coca_cola_stock_closing_price/
So the first thing I did was scale my numbers. Having price points in the tens of dollars, and volume in the millions blew up my model pretty badly. My previous unscaled version had errors relative to my training data in the 10’s of dollars per week.
I scaled volume to shares outstanding, and share price to % change, and it looks like this model is performing better. The scaled model has errors much tighter. I’ve attached a histogram of my model’s error using the last 100 week’s of data. Next Friday will be the first real test though.
So the bad news. I define success as my model performing better than a “Lazy” predictor, which assumes that next week’s closing price will equal this week’s closing price. My model’s error histogram pretty much sits exactly on top of the Lazy predictor histogram.
Comparing root mean square error, my LSTM predictor is actually slightly worse…
There are a few known issues that I need to work out. I haven’t included dividend data, nor do I have a method to handle splits. I’ll need to be able to address splits if I want to include other companies.
Data is starting to get a bit messy to handle. I’m currently stuck doing some manual manipulation and manual data entry, as Alphavantage is missing historical shares outstanding. Ideally I would include float as well.
Looks like I might need to setup a SQL server locally to host all this data.
I’m starting to understand why many of the tutorials spend 80% of their time on data manipulation and only 20% on tensorflow.
submitted by /u/squirrelaway4all
[visit reddit] [comments]
|
submitted by /u/biswajitsahoo1111 [visit reddit] [comments] |
 Computer-generated holograms powered by deep learning could make real-time 3D holography feasible on laptops and smartphones, an advancement with potential applications in fields including virtual reality, microscopy, and 3D printing.
Published this week in Nature, an MIT study outlines a novel approach called tensor holography, where researchers trained and optimized a convolutional neural network to create holograms from images with depth information. The compact network requires under 1 MB of memory, and crafts holograms within milliseconds.
“People previously thought that with existing consumer-grade hardware, it was impossible to do real-time 3D holography computations,” said lead author Liang Shi, Ph.D. student in MIT’s Department of Electrical Engineering and Computer Science. “It’s often been said that commercially available holographic displays will be around in 10 years, yet this statement has been around for decades.”
Old-school holograms use laser beams to depict a static scene with both colors and a sense of depth. Traditionally, computer-generated holography has relied on supercomputers to simulate this optical set up, making it possible to create digital holograms that can also capture motion and be easily reproduced and shared.
Simulating the underlying physics of a hologram, however, is computationally intensive, taking up to minutes to render a single holographic image on a clustered supercomputer.
“Because each point in the scene has a different depth, you can’t apply the same operations for all of them,” Shi said. “That increases the complexity significantly.”
To speed things up, and increase the photorealistic precision of the holograms, the researchers turned to deep learning.
The team created custom high-quality training data — the first such database for 3D holograms — made up of 4,000 images with depth information, and a corresponding 3D hologram for each image. Training on NVIDIA Tensor Core GPUs, the CNN learned to generate accurate holograms from images with depth information, which can be acquired by standard modern smartphones with multi-camera setups or LiDAR sensors.
Using an NVIDIA TITAN RTX GPU and the NVIDIA TensorRT SDK for inference, the optimized neural network runs in real time, achieving a speedup of more than two orders of magnitude compared to physical simulation. The final model uses just 617 kilobytes of memory, allowing it to run interactively on low-power AI chips on mobile and edge devices.
The resulting method not only accelerated the process, but also produced holograms with accurate occlusion and per-pixel focal control, improving the images’ realism.
Read the news release from MIT and visit the researchers’ project page. The full paper can be found in Nature.
 Thrust 1.12.0 and CUB 1.12.0 are distributed with the NVIDIA HPC SDK 21.3 and the CUDA Toolkit 11.4.
Thrust 1.12.0 is a major release providing bug fixes and performance enhancements. It includes a new thrust::universal_vector which holds data that is accessible from both host and device. This enables the use of CUDA unified memory with Thrust. Also added are new asynchronous versions of thrust::async:exclusive_scan and inclusive_scan algorithms. The synchronous versions of these have been updated to use cub::DeviceScan directly. This release deprecates support for Clang
CUB 1.12.0 is a major release providing bug fixes and performance enhancements. It includes improved Radix sort stability. Please see the CUB 1.12 Release Notes for more information.
Both packages are available today from GitHub. They are also distributed with the NVIDIA HPC SDK 21.3 and the CUDA Toolkit 11.4.
About Thrust and CUB
Thrust is a modern C++ parallel algorithms library which provides a std::-like interface. Thrust abstractions are agnostic of any particular parallel programming model or hardware. With Thrust, you can write code once and run it in parallel on either your CPU or GPU. CUB is a C++ library of collective primitives and utilities for parallel algorithm authors. CUB is specific to CUDA C++ and its interfaces explicitly accommodate CUDA-specific features.
Thrust and CUB are complementary and are often used together.
Learn more: