Categories
Offsites

Virtual consensus in Delos

Virtual consensus in Delos, Balakrishnan et al. (Facebook, Inc.), OSDI’2020

Before we dive into this paper, if you click on the link above and then download and open up the paper pdf you might notice the familiar red/orange splash of USENIX, and appreciate the fully open access. USENIX is a nonprofit organisation committed to making content and research freely available – both conference proceedings and the recorded presentations of their events. Without in-person conferences this year, income is down and events are under threat. If you want to help them, you have options to donate, become a member, or even talk to your organisation about becoming a partner, benefactor, or patron. Every little helps!

Back in 2017 the engineering team at Facebook had a problem. They needed a table store to power core control plane services, which meant strong guarantees on durability, consistency, and availability. They also needed it fast – the goal was to be in production within 6 to 9 months. While ultimately this new system should be able to take advantage of the latest advances in consensus for improved performance, that’s not realistic given a 6-9 month in-production target. So realistically all that could be done was to choose an existing consensus implementation and integrate it. Integrating an existing implementation brings problems of its own though:

Laying the system over an existing shared log such as LogDevice would allow us to reach production quickly, but also tie us for perpetuity to the fault-tolerance and performance properties of that consensus implementation.

What Facebook needed, literally, was a plan to throw one away. I.e., a plan that let them get into production quickly with an existing implementation, and then be able to upgrade it later without disturbing system operation (nobody wants to take down the central control plane for maintenance!). This calls for the oldest tool in the box: a level of indirection. In other words, an API based abstraction over consensus, together with a runtime that supports hot-swapping of those implementations. The standout candidate as the API for consensus is the shared log.

Recently, the shared log has gained traction as an API for consensus in research and industry. Applications can replicate state via this API by appending updates to the shared log, checking its tail, and reading back updates from it. The consensus protocol is hidden behind the shared log API, allowing applications to bind to any implementation at deployment time.

Behind the shared log API is a log abstraction that maps log positions to log entries. If you think of this a bit like mapping memory addresses to data in memory, then another parallel comes to mind: the virtual address space. One logical log, but with different portions of the log address space mapped to different backing shared log instances. This is the core idea in Delos, a VirtualLog that virtualises consensus.

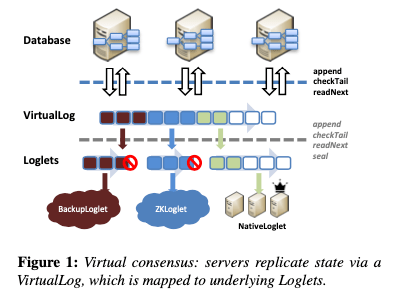
We propose the novel abstraction of a virtual shared log (or VirtualLog). The VirtualLog exposes a conventional shared log API; applications above it are oblivious to its virtualized nature. Under the hood, the VirtualLog chains multiple shared log instances (called Loglets) into a single shared log.
It’s such a powerful idea that I can imagine distributed systems implementers everywhere adopting it from now on. What does the VirtualLog give us?

Firstly, it solves the upgrade problem. We have an existing Loglet writing log entries into the address space. To upgrade, the portion of the address space managed by this Loglet is sealed to prevent further writes, and then the Loglet chain is reconfigured to add the new Loglet at the tail. That’s not just theoretical, Facebook actually did this in production while Delos was processing over 1.8 billion transactions per day. The initial version of Delos went into production after eight months using a ZooKeeper-backed Loglet implementation, and then four months later it was swapped out for a new custom-built NativeLoglet that gave a 10x improvement in end-to-end latency.

Once you have a trusted reconfiguration protocol to move from one Loglet chain configuration to another, you can do lots of interesting things. For example, Loglets might be instances of the same ordering protocol, but with different parameters, or they could be entirely different log implementations (e.g. replacing Paxos with Raft), or they could be shims over external storage systems. If you have an existing implementation with its own leader elections, internal reconfiguration, and epochs that can sit happily under the Loglet abstraction. But critically, Loglets no longer need to handle all of that complexity:

While the VirtualLog’s reconfiguration mechanism can be used solely for migrating between entirely different Loglet implementations, it can also switch between different instances of the same Loglet protocol with changes to leadership, roles, parameters, and membership. As a result, the Loglet itself can be a statically configured protocol, without any internal support for reconfiguration. In fact, the Loglet does not even have to implement fault-tolerant consensus (i.e. be highly available for appends via leader election), as long as it provides a fault tolerant seal command, which is theoretically weaker and simpler to implement.

This separation of concerns moves reconfiguration into the VirtualLog control plane, leaving Loglets responsible for the data plane. It makes reconfiguration easier as well as simplifying the implementation of Loglets. If a Loglet fails for appends, it is simply sealed and the VirtualLog switches to a new Loglet.

Sealing

A minimal Loglet needs to provide totally ordered, durable storage via the shared log API. It can do this within a static configuration with no support for role or membership changes and no leader election. What it must provide however, is a highly available seal command that prevents any new appends from being acknowledged.

Once sealed, a Loglet can never be unsealed. So we have a couple of handy properties that make implementing seal much easier than a general purpose highly available append: only one value can ever be proposed, and that value is sticky. In Facebook’s implementation of NativeLoglet, seal simply sets a bit on a quorum of servers.

In addition to seal, a minimal Loglet is also responsible for its own failure detection, asking the VirtualLog to reconfigure when a failure is detected, and supplying a new Loglet configuration minus the failed servers.

Reconfiguration

Existing consensus systems often store the configuration and epoch information inline in the same totally ordered log as other commands. For VirtualLog, that would mean writing the configuration for the new Loglet inside the log address space of the outgoing Loglet before it is sealed. And that would put more complexity onto Loglets, requiring them to be highly available for appends, not just seal.

The VirtualLog uses a separate MetaStore instead, whose job is to manage the configuration of the VirtualLog over time. Because reconfiguration happens less frequently than regular command sequencing, the consensus protocol for reconfiguration can favour simplicity over out-and-out performance. For Facebook’s Delos, reconfiguration latencies of 10s of ms are ok.

The MetaStore exposes a single versioned register supporting a conditional write: writing requires supplying a new value and an expected existing version. Any client can initiate a reconfiguration, or complete a reconfiguration begun by another client. Reconfiguration has three steps:

  1. The client seals the current chain by sealing its active segment. A call to checkTail will now return the start of a new active segment. This is an idempotent operation.
  2. The reconfiguring client writes a new chain to the MetaStore. Because of the conditional write, if multiple clients are racing to reconfigure, at most one one can win.
  3. The reconfiguring client fetches the new chain from the MetaStore (in the case where its write failed in step 2).

Clients trying to write to the old active segment after step 1 will receive a ‘sealed’ error code, and can retry after fetching the latest chain from the MetaStore.

The NativeLoglet

Delos currently supports three disaggregated Loglets acting as shims over external services (ZooKeeper, a LogDevice service, and a Backup service used for cold storage). It also has two of its own Loglet implementations that can be run either converged or disaggregated: the NativeLoglet and the StripingLoglet.
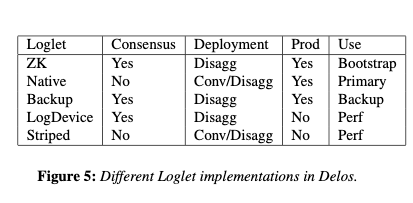
In production, Facebook use the NativeLoglet in converged form. NativeLoglet implements seal by setting a bit on a quorum of servers. It uses a a central sequencer to assign positions to commands and forward requests to LogServers. An append is considered globally committed once a majority acknowledge. If the sequencer fails, NativeLoglet simply becomes unavailable for appends.

Practically, we found this protocol much easier to implement than fault-tolerant consensus: it took just under 4 months to implement and deploy a production-quality native Loglet.

Striping Loglets

The StripedLoglet is where things start to get even more interesting. A StripedLoglet is responsible for one portion of the global log address space, but internally it further maps (stripes) that portion over multiple nested Loglets.
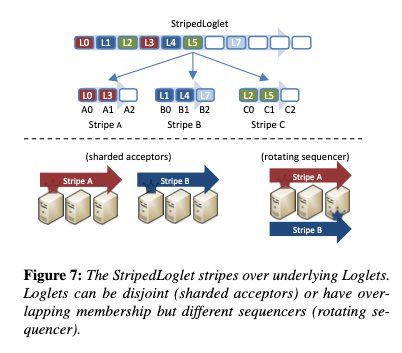
This provides a simple way (about 300 loc) to scale throughput. For example, a shared sequencer bottleneck can be relieved by introducing a rotating sequencer – multiple sequencers dividing an address space between them and sharing the same underling LogServers. Alternatively, the address space can mapped to multiple underlying LogServer clusters to increase throughput.

Even though it is a composite, a StripedLoglet must still be sealed as a whole even if only one of its stripes needs to be reconfigured.

Delos in production

The evaluation section has lots of good information on experiences running Delos in production, as well as some synthetic benchmarks. The in-production switch from a ZK Loglet to NativeLoglet was done for the first time on April 2nd 2019, and gave a 10x improvement at p99 for gets, and a 5x improvement for writes.

My favourite example here is a really cool use case for reconfiguration. Most of the time Delos runs with a converged Loglet implementation, since this reduces the external dependencies of a very critical system. Under a log spike though, it can be reconfigured to run with a disaggregated Loglet, giving higher throughput. A related example is when Delos is running in converged mode and e.g. two of the five converged database replicas crash. Now the database and the shared log are fate-sharing and at risk if one more node is lost…

In this situation (which was not uncommon), we found it valuable to reconfigure the system to a disaggregated log, temporarily decoupling the fate of the database and the log. Once the database was restored to five replicas, we reconfigured back.

The overheads of virtualisation are pleasingly low: about 100-150µs at p99 latency, 10s of ms for reconfiguration, and no impact on peak throughput.

Limitations and future work

It all sounds pretty amazing doesn’t it! There are a couple of limitations: (1) consensus protocols that exploit speculation or commutativity don’t currently fit under the Loglet API. “In future work, we plan to extend virtual consensus to partially ordered shared logs.”, and (2) there’s a latency hit for VirtualLog-driven reconfiguration which may or may not be important in your scenario.
Categories
Offsites

Helios: hyperscale indexing for the cloud & edge (part II)

Helios: hyperscale indexing for the cloud & edge, Potharaju et al., PVLDB’20

Last time out we looked at the motivations for a new reference blueprint for large-scale data processing, as embodied by Helios. Today we’re going to dive into the details of Helios itself. As a reminder:

Helios is a distributed, highly-scalable system used at Microsoft for flexible ingestion, indexing, and aggregation of large streams of real-time data that is designed to plug into relationals engines. The system collects close to a quadrillion events indexing approximately 16 trillion search keys per day from hundreds of thousands of machines across tens of data centres around the world.

As an ingestion and indexing system, Helios separates ingestion and indexing and introduces a novel bottoms-up index construction algorithm. It exposes tables and secondary indices for use by relational query engines through standard access path selection mechanisms during query optimisation. As a reference blueprint, Helios’ main feature is the ability to move computation to the edge.

Requirements

Helios is designed to ingest, index, and aggregate large streams of real-time data (tens of petabytes a day). For example, the log data generated by Azure Cosmos. It supports key use cases such as finding records relating to specific attributes (e.g. for incident support), impact and drill-down analysis, and performance monitoring and reporting. One interesting use case is in support of GDPR right to be forgotten requests, where it becomes necessary to search 10s of billions of streams to find those containing a user’s information.

Incoming streams can have data rates as high as 4TB/minute, with many columns to be indexed (7+ is common) and high cardinality.

System design

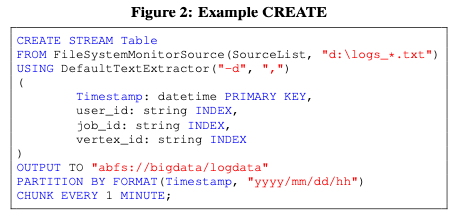
A stream table is defined by a loose schema which defines the sources to be monitored (as a SourceList) and indices to be created. For example:

Based on the CREATE STREAM statement, Helios generates an agent executable to be deployed on every machine producing a log that is part of the stream. It also generates an executable to be run on the server-side ingestion machines. The agent process accumulates and chunks incoming data into data blocks (with frequency determined by the CHUNK EVERY clause). Optionally, and central to how Helios handles high volume and velocity ingest at manageable scale and cost, the agent can also perform local processing (parsing, indexing, and aggregation) and send the resulting index entries to the ingestion clusters in a compact format.

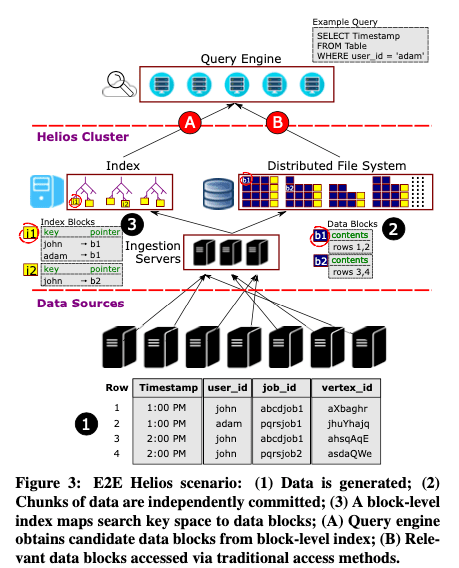
Ingestion servers are stateless, running the user-defined dataflow (based on the CREATE SCHEMA statement) to process incoming blocks. Data blocks are stored in a distributed file system, and once acknowledged by the file system, an entry is written into Helio’s progress log. The progress log is used to track the progress of both data ingestion and index building. Secondary index generation (hydration) then happens asynchronously. The resulting index blocks are merged into a global index which maps (column, value) pairs to data block URIs.

The progress log is the only strongly synchronized component in Helios, and is deployed in quorum based rings of 5 servers. There are multiple replicated logs each governing a partition of the data set. In this manner Helios achieves a consistent rate of 55,000 writes/second for metadata persistence.

Indexing

A key factor in Helios’s success is asynchronous index mangement: Helios maintains eventually consistent indexes against the data, but exposes a strongly consistent queryable view of the underlaying data with best-effort index support.

Helios’ index is a multi-level (tree-based) structure that is built in a bottom-upmanner. I.e., information is inserted at the leaves, and the index then ‘grows upwards’ through merge and add operations. The authors point out an interesting similarity to learned index structures here: “At the highest level, a learned index tries to learn a function that maps an index search key to the leaf nodes containing the search key. The Helios structure in its generic form performs exactly the same function, with the different that the mapping is not learned from data but composed from the (typically, hash) partitioning functions used by the different index levels.“

Indexing begins by scanning the progress log from the latest checkpoint, with an initial leaf node at the bottom of the tree (level 0) constructed for each chunk. No global order is imposed here, indexed keys are simply packed into leaf nodes based on arrival order. Multiple nodes at the same level may be combined into one using the merge operator in accordance with a merge policy. Just as level 0 watches blocks arrive in the progress log and follows along creating leaf nodes, so the next level up, level 1 watches the progress of leaf nodes arriving at level 0, and creates a higher level index over the leaf nodes by applying the add operator. Level 2 follows the progress of level 1 in a similar manner, and so on for the desired number of levels. The result is an indexing frontier that moves forward across the levels through a per-level watermark.

An index node is a collection of (key, pointers) pairs. The merge operation combines two index nodes N_1  and N_2 by taking the union of their keys, and for each key the union of the pointers. E.g. if N_1 = {K_1 mapsto {P_1, P_2}, K_2 mapsto {P_3}} and N_2 = {K_2 mapsto {P_4}} then N_1 oplus N_2 = { K_1 mapsto {P_1, P_2}, K_2 mapsto {P_3, P_4 }}. Helios uses a size-based merge policy in which two nodes are merged if they are both below a given size threshold.

The add operation creates a new node at one level up containing the union of the keys in the blocks being added, and pointers to the nodes in the level below containing entries for those keys. E.g. N_1 + N_2 = {K_1 mapsto {P_{N_1}}, K_2 mapsto {P_{N_1}, P_{N_2}}}. Helios also uses a size-based add policy, in which nodes are added (at higher and higher levels) until the size of the resulting node reaches a configurable threshold.

Note that the resulting structure may contain orphan nodes (shown in grey in the figure above) that do not have any parent in the layer above. This has implications for query processing that we’ll look at shortly.

Index compaction, which also takes place bottom-up, is triggered when a configurable number of data blocks have been processed.

Federated indexing

Our initial approach towards data and index management focused towards bringing in data from all the sources into an ingestion cluster and performing the required post-processing operations (e.g. parsing, indexing, etc.). However, this approach incurs significant costs… The hierarchical/recursive indexing model gives the freedom of distributing our computation acress the agents and ingestion back-end servers, sharing the same intuition as the current trend of edge computation.

Pre-processing on agents reduces the size of the ingestion cluster required, at the cost of consuming processing power on the source machine. In Helios production deployments, the agent typically consumes 15%-65% of a single CPU core, and stays under an allocated memory budget of 1.6GB. The generated agent and ingestion code utilises a shared library called Quarkwhich provides a selection of parsers, extractors, indexers, partitioners, serializers and compressors as well as query-processing operators with predicate push-down.

Querying

Helios indexes are represented and exposed as data in easily accessible formats, available for any query engine. This allows us to democratise index usage outside of Helios, e.g. query engines can perform their own cost-based index access path selection, and index reads can independently scale without being constrained by compute resources provided by Helios. In fact, we were able to integrate Apache Spark with no changes to its optimizer/compiler.

Due to the existence of orphan nodes, querying can’t proceed in a pure top-down manner. So Helios provides a hybrid index scan operator. Querying starts by moving down the tree from the root nodes (which are orphan nodes by definition), and then recursively repeating this process for each of the orphan nodes at the next level down moving right.

In Figure 6 above for example, we can search down the tree from N_{21}, but in doing so we miss any potential hits in the orphan node N_{13} at the next level down. So after processing N_{21} we start a new search from N_{13}. This in turn may miss hits in the orphan block N_{08} so we then drop-down once more and move right…
Helios in production

Helios has multiple uses at Microsoft including supporting debugging and diagnostics, workload characterization, cluster health monitoring, deriving business insights, and performing impact analysis.

Helios clusters have been in production for the last five years, collecting close to a quadrillion log lines per day from hundreds of thousands of machines spread across tens of datacenters.

Categories
Offsites

Covering 10 points, a surprisingly tricky puzzle.

Categories
Offsites

Escher’s most mind-bending piece

Categories
Offsites

The ants and the pheromones

TLDR; this is the last edition of The Morning Paper for now. Plus: one strand of research you won’t want to miss!

I was listening to a BBC Radio 4 podcast recently (More or Less: Behind the Stats – Ants and Algorithms) in which the host Tim Harford is interviewing David Sumpter about his recent book, ‘The ten equations that rule the world.’ One of those equations, the ‘reward equation’ models how ants communicate using pheromones, and our own brains keep track of rewards using dopamine.

About 4 and a half minutes into the podcast Tim asks a fascinating question: the reward equation includes a decay or ‘forgetting’ parameter, so what happens if you disrupt established solutions for long enough that their hold is broken? For example, the complete disruption to our established routines that Covid has caused over the last year? The answer for ants, if you disrupt all of the pheromone trails around their nest, is that they converge on a new solution in the environment, but it won’t necessarily look the same as the one they had before the disruption. (If you’re interested in the amazing problem-solving skills of ants and how we can learn from them in computer science, I covered ‘Ant algorithms for discrete optimization’ in a previous edition of The Morning Paper). It’s highly likely that the same thing will happen to us when we can eventually return to normal – the patterns that we establish won’t necessarily be the same as the ones we had before the series of lockdowns began.

The lockdowns (as I write this, we’re in another strict lockdown in England, with no end date given) have certainly disrupted my own routines. I’ve lost the time and space that I depended on for studying and writing The Morning Paper – the one-hour each way train journey on my morning commute, and more crucially with two older children both full-time studying from home, the time and space within the home for the many hours of concentrated work required. I don’t think my love of learning will ever leave me though, and at the same time I’ve been branching out and studying other things: philosophy, ethics, physics, a little maths, a little biology,… I’m really enjoying that. My love of computer science remains of course, but when we finally get to lay down our new pheromone trails and establish a new normal, I’m not sure I’m going to want to focus on computer science to the exclusion of all else. It’s been an intense six-and-a-half years doing largely that while writing the blog. For the time being then, I’m putting The Morning Paper back on pause.

Before I wrap up though, I can’t resist pointing you in the direction of one incredibly exciting research project from the Hydro team at Berkeley’s RISELab. Joe Hellerstein recently posted a whole bunch of links and resources in this Twitter thread:

I’m super excited about the new chapter emerging in our research on a programmable cloud. This is what comes after serverless, people. 

In this thread, a few recent talks/papers on the vision. First off — 10 minute pitch from CIDR is here. https://t.co/fEMboOGF7Q— Joe Hellerstein (@joe_hellerstein) January 28, 2021

The “PACT” paper is here: New Directions in Cloud Programming, Cheung et al., CIDR 2021.

Categories
Offsites

An overview of end-to-end entity resolution for big data

An overview of end-to-end entity resolution for big data, Christophides et al., ACM Computing Surveys, Dec. 2020, Article No. 127

The ACM Computing Surveys are always a great way to get a quick orientation in a new subject area, and hot off the press is this survey on the entity resolution (aka record linking) problem. It’s an important part of many modern data workflows, and an area I’ve been wrestling with in one of my own projects.

Entity Resolution (ER) aims to identify different descriptions that refer to the same real-world entity appearing either within or across data sources, when unique entity identifiers are not available.

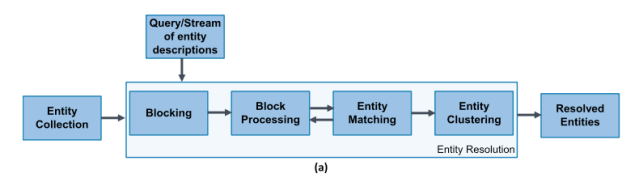
When ER is applied to records from the same data source it can be used for deduplication, when used to join records across data sources we call it record linking. Doing this well at scale is non-trivial; at its core, the problem requires comparing each entity to every other, i.e. it is quadratic in input size.An individual record/document for an entity is called an entity description. A set of such descriptions is an entity collection. Two descriptions that correspond to the same real world entity are called matches or duplicates. The general flow of an ER pipeline looks like this:

  • Blocking takes input entity descriptions and assigns them to one or more blocks based on blocking keys. The point of blocking is to reduce the number of comparisons that have to be made later on – the key idea is that any two entity descriptions that have a chance of referring to the same real-world entity should end up in the same block under at least one of the blocking keys. Therefore we only have to do more detailed comparisons within blocks, but not across blocks. “The key is redundancy, i.e., the act of placing every entity into multiple blocks, thus increasing the likelihood that matching entities co-occur in at least one block.”
  • Block processing then strives to further reduce the number of comparisons that will need to be made by eliminating redundantcomparisons that occur in multiple blocks, and superfluous comparisons within blocks.
  • Matching takes each pair of entity descriptions from a block and applies a similarity function to determine if they refer to the same real-world entity or not. (In an iterative ER process, matching and blocking may be interleaved with the results of each iteration potentially impacting the blocks).
  • Clustering groups together all of the identified matches such that all the descriptions within a cluster refer to the same real-world entity. The clustering stage may infer additional indirect matching relations.

The resulting clusters partition the input entity collections into a set of resolved entities.

ER solutions can be classified along three dimensions:

  • Schema-awareness – is there a schema to give structure to the data or not?
  • The nature of the matching process – is it based on a comparison of attributes in the entity descriptions, or is there more complex matching going on such as comparing related entities to give further confidence in matching?
  • The processing mode – traditional batch (with or without budget constraints), or incremental.

Let’s dive into each of the major pipeline stages in turn to get a feel for what’s involved…

Blocking

There’s a whole separate survey dedicated just to the problem of blocking for relational data, so in this survey the authors focus their attention on blocking for schema-less data. There are lots of different approaches to this:

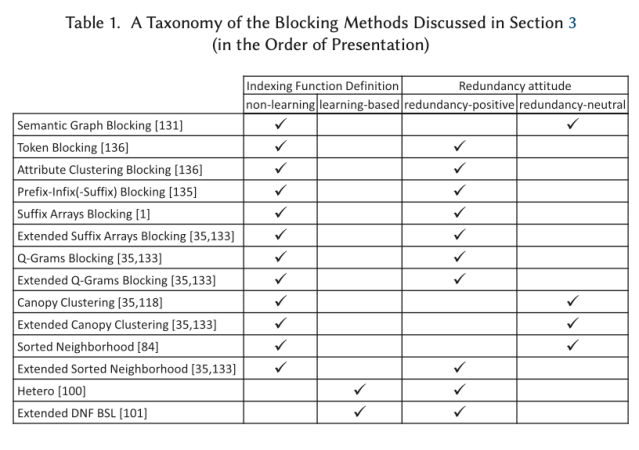
Classic approaches look at relations and attributes. For example Token Blocking makes one block for each unique token in values, regardless of the attribute. Any entity with that token in the value of any attribute is added to the block. Redundancy positive blocking schemes such as token blocking are those in which the probability that two descriptions match increases with the number of blocks that include both of them. For redundancy neutral schemes this is not the case. An example of a redundancy neutral scheme is Canopy Clustering, which uses token-based blocks, but assigns an entity to a block based on a similarity score being greater than a threshold T_{in} Moreover, if the similarity score exceeds t_{ex} (> t_{in}) then the description is not added to any further blocks.

Block processing

As with blocking, there are a multiplicity of approaches to block processing. Block cleaning methods may purge excessively large blocks (as these are likely to be the result of common stop-word tokens and hence less useful for matching) and filter the blocks a given description is present in – for example by removing the description from the largest r of the blocks it appears in. More sophisticated methods may also split and merge blocks. Dynamicapproaches schedule block processing on the fly to maximise efficiency.
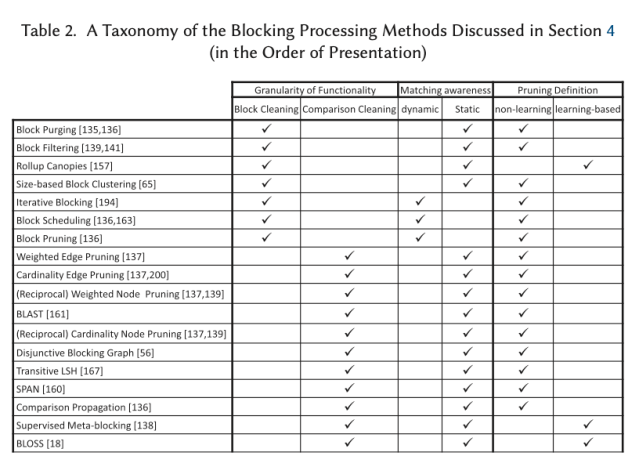
Comparison cleaning methods work on redundancy positive block collections. A graph is constructed where nodes are entity descriptions, and there is an edge between every pair of nodes co-located in a block, with an edge weight representing the likelihood of a match, e.g. the number of blocks they are co-located in. Once the graph is constructed, edge-pruning can be used to remove lower weighted edges. There are a variety of strategies both for weighting and for pruning edges. For example, Weighted Edge Pruningremoves all edges less than or equal to the average edge weight. After pruning, new blocks are created from the retained edges. Learning-based methods train classifiers for pruning.

Matching

A matching function M takes a pair of entity descriptions and measures their similarity using some similarity function sim. If the similarity score exceeds a given threshold they are said to match, otherwise they do not match. In a refinement the match function may also return uncertain for middling scores. The similarity function could be atomic, such as Jaccard similarity, or composite (e.g., using a linear combination of several similarity functions on different attributes). Any similarity measure that satisfies non-negativity, identity, symmetry, and triangle inequality can be used.
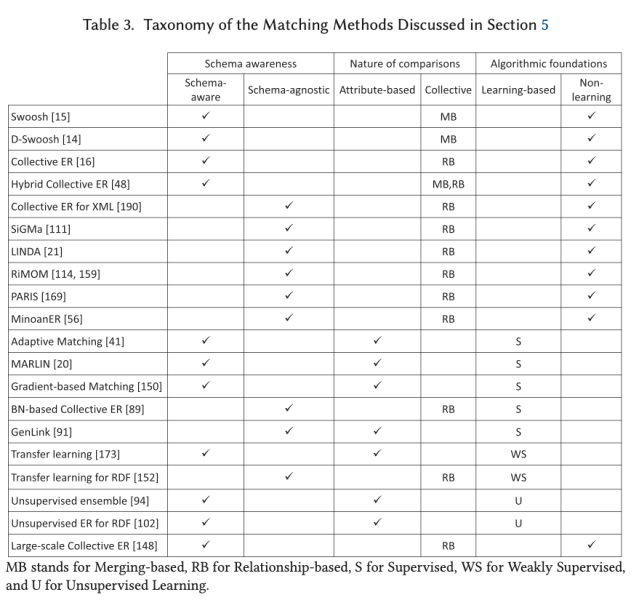
Collective based matching processes use an iterative process to uncover new matches as a result of matches already made. Merging-based collective techniques create a new entity description based on merging a matched pair, removing the original paired descriptions. Relationship-based collective techniques use relationships in the original entity graph to provide further similarity evidence. For example, Collective ER…

Collective ER employs an entity graph, following the intution that two nodes are more likely to match, if their edges connect to nodes corresponding to the same entity. To capture this iterative intuitive, hierarchical agglomerative clustering is performed, where, at each iteration, the two most similar clusters are merged, until the similarity of the most similar cluster is below a threshold.

A variety of supervised, semi-supervised, and unsupervised matching techniques have also been developed.

The output of the matching process is a similarity graph with nodes corresponding to descriptions and edges connecting descriptions that matched, weighted by the matching probability.

Clustering

Clustering aims to infer more edges from indirect matching relations, while discarding edges that are unlikely to connect duplicates in favor of edges with higher weights. Hence, its end result is a set of entity clusters, each of which comprises all descriptions that correspond to the same, distinct real-world object.

The simplest approach is just to find Connected Components, but generally more advanced clustering techniques are used. For example, Markov Clustering uses random walks to strengthen intra-cluster edges while weakening inter-cluster ones.

Making it incremental

Section 8 in the survey discusses incremental approaches, but my general takeaway is that these seem rather thin on the ground, and mostly oriented towards assembling the information needed to answer an incoming query on the fly. The exception is Incremental Correlation Clustering which updates the clustering results on the fly based on newly created, updated, and deleted descriptions. All of the discussed approaches require schemas.

Open source ER systems

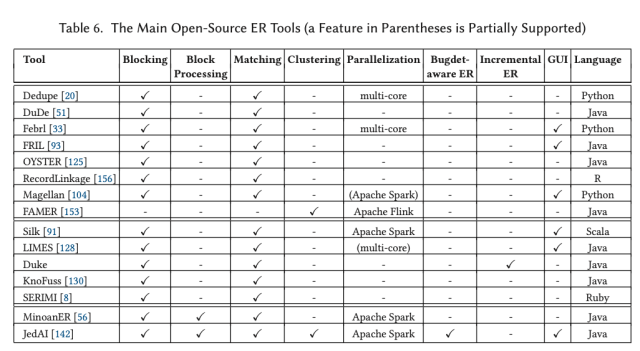
The survey includes an assessment of open source tools for ER, summarised in the table below.

…we share the view of ER as an engineering task by nature, and hence, we cannot just keep developing ER algorithms in a vacuum. In the Big Data era, we opt for open-world ER systemsthat allow one to plug-and-play different algorithms and can easily integrate with third-party tools for data exploration, data cleaning, or data analytics.

Categories
Offsites

But what is cross-entropy? | Compression is Intelligence Part 2

Categories
Offsites

100 random chords, how many intersections?

Categories
Offsites

Measuring the entropy of English

Categories
Offsites

What’s the perfect encoding? How do you know?