
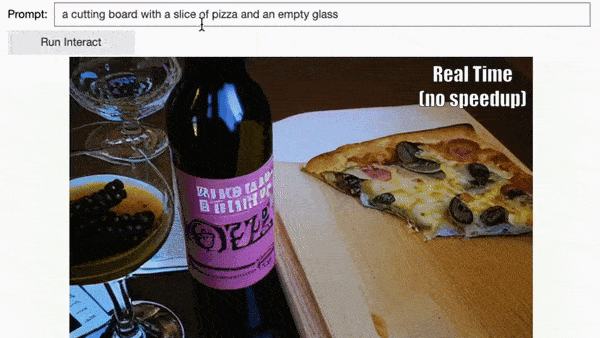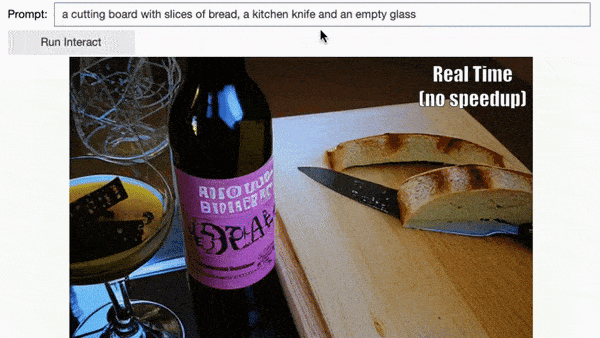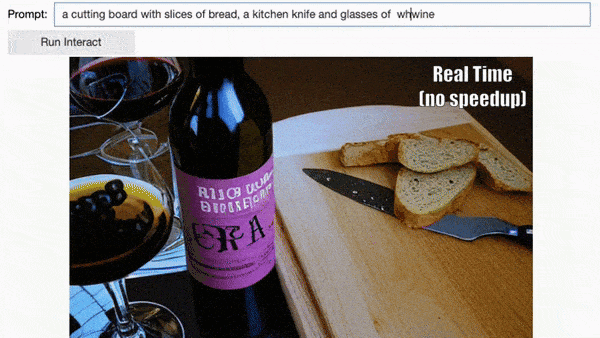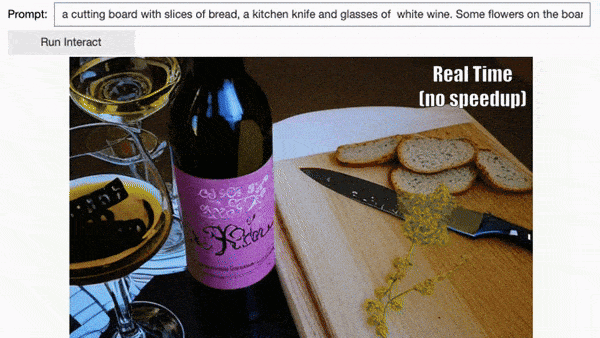
 Text-to-image diffusion models can generate diverse, high-fidelity images based on user-provided text prompts. They operate by mapping a random sample from a…
Text-to-image diffusion models can generate diverse, high-fidelity images based on user-provided text prompts. They operate by mapping a random sample from a high-dimensional space, conditioned on a user-provided text prompt, through a series of denoising steps. This results in a representation of the corresponding image, . These models can also be used for more complex tasks such as image…
 The International Society of Automation (ISA) reports that 5% of plant production is lost annually due to downtime. Putting that into a different context,…
 Driven by shifts in consumer behavior and the pandemic, e-commerce continues its explosive growth and transformation. As a result, logistics and transportation…
 To fully harness the capabilities of NVIDIA GPUs, optimizing NVIDIA CUDA performance is essential, particularly for developers new to GPU programming. This talk…
 RAPIDS 24.08 is now available with significant updates geared towards processing larger workloads and seamless CPU/GPU interoperability.
 The Llama 3.1 405B large language model (LLM), developed by Meta, is an open-source community model that delivers state-of-the-art performance and supports a…