
 Six years ago, we embarked on a journey to develop an AI inference serving solution specifically designed for high-throughput and time-sensitive production use…
Six years ago, we embarked on a journey to develop an AI inference serving solution specifically designed for high-throughput and time-sensitive production use cases from the ground up. At that time, ML developers were deploying bespoke, framework-specific AI solutions, which were driving up their operational costs and not meeting their latency and throughput service level agreements.
 Large language model (LLM) inference is a full-stack challenge. Powerful GPUs, high-bandwidth GPU-to-GPU interconnects, efficient acceleration libraries, and a…
 Trillions of PDF files are generated every year, each file likely consisting of multiple pages filled with various content types, including text, images,…
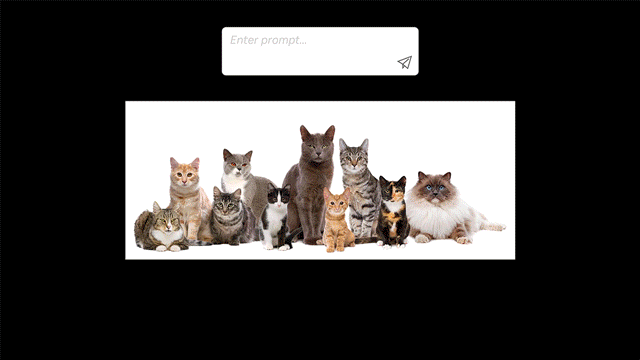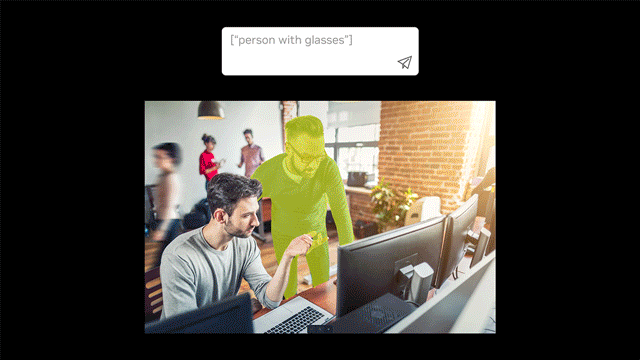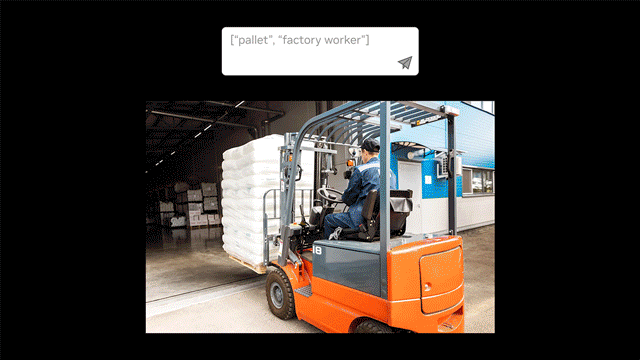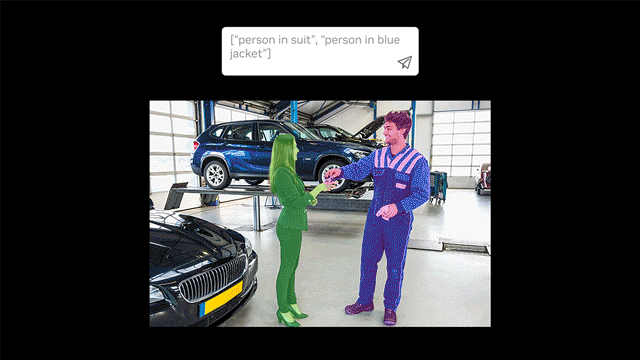 NVIDIA TAO is a framework designed to simplify and accelerate the development and deployment of AI models. It enables you to use pretrained models, fine-tune…
 Today’s large language models (LLMs) achieve unprecedented results across many use cases. Yet, application developers often need to customize and tune these…
 As large language models (LLMs) continue to grow in size and complexity, multi-GPU compute is a must-have to deliver the low latency and high throughput that…
 This post is the third in a series on building multi-camera tracking vision AI applications. We introduce the overall end-to-end workflow and fine-tuning…